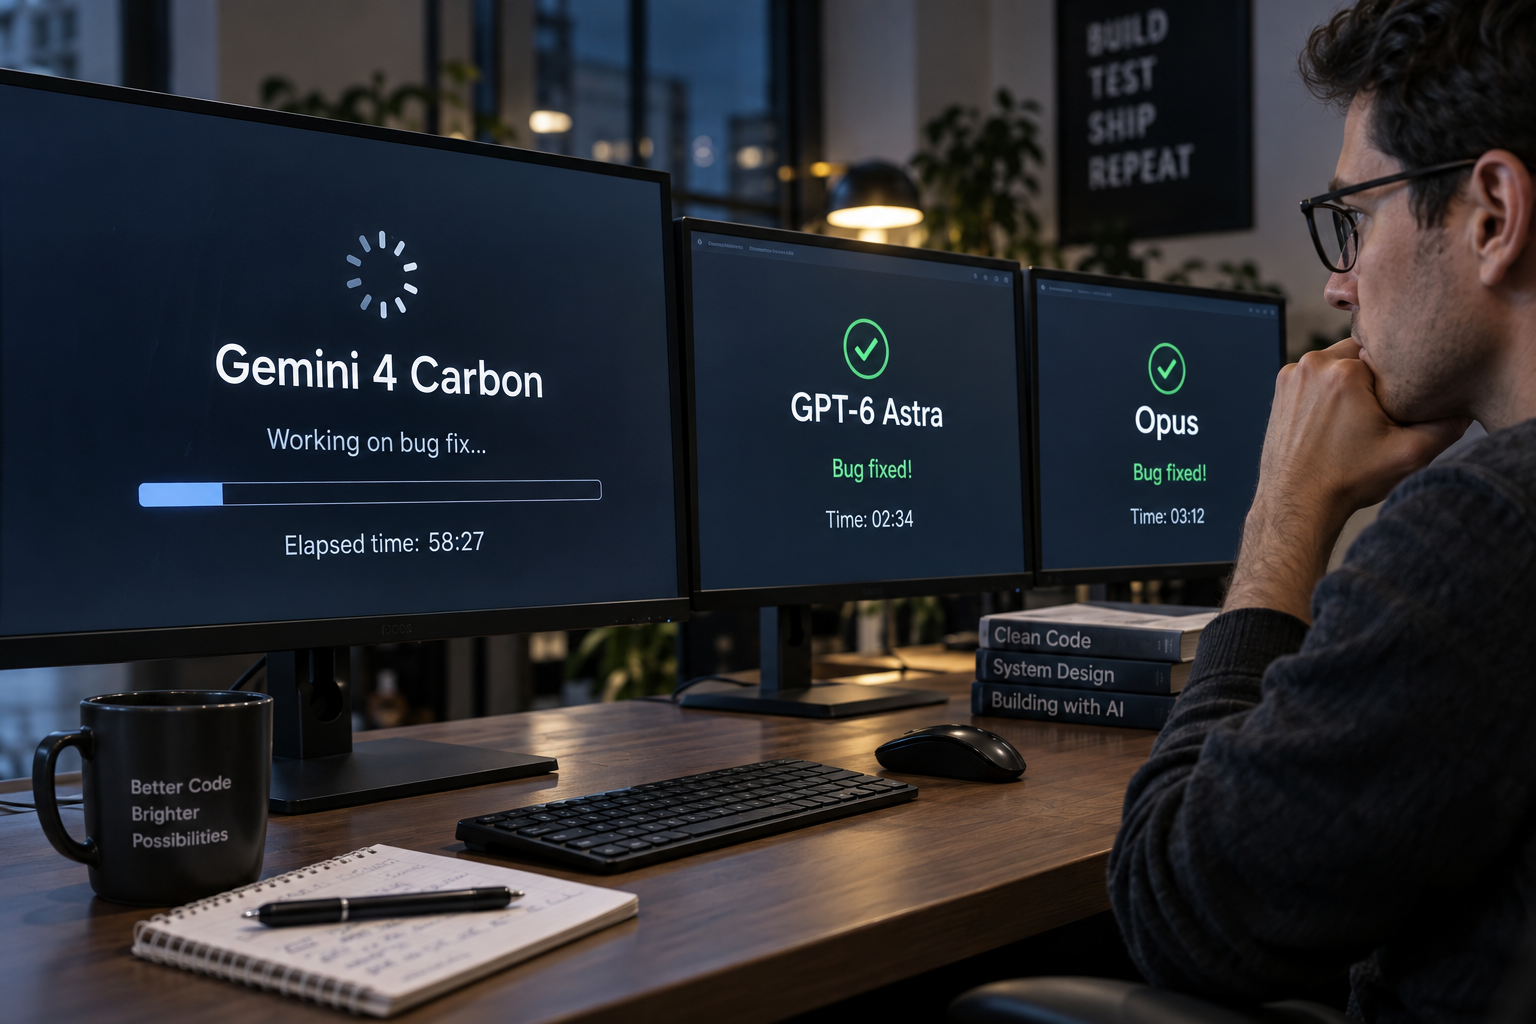
Gemini 4 Carbon spent close to an hour on bug-fixing tasks that Opus and GPT-6 Astra usually finished in a few minutes. The gap showed up during a benchmark run on one of the team's private evaluations, and it was big enough that the team decided to find out what was happening inside the model's runs.
The test is straightforward. Each agent receives a codebase from just before a bug was fixed, along with a report that describes the problem only by its symptoms. The agent must diagnose the bug and fix it without making unrelated changes. Much of the difficulty lies in engineering judgment: tracing symptoms to the right code path, ruling out rival explanations, placing the fix in the right spot and knowing when to stop.
Why does Gemini 4 Carbon take longer on bug fixes?
Slower responses explain only part of the delay. Inference speed, which covers queueing at the provider, network latency and processing time, accounted for 16 to 30 percent of Carbon's extra time compared with Astra, and 45 to 49 percent compared with Opus. The remainder came from longer runs. Carbon took about seven times as many steps as Astra and eleven times as many actions, such as reading a file or running a command. It wrote seven times as much text. Because each step resent a longer and longer conversation, it also processed more than sixteen times as much input.
Before digging into the traces, the team ruled out two simpler explanations. It ran Carbon inside two other coding agents, opencode and mini-SWE-agent, and saw no meaningful difference. It also considered whether the comparison was unfair, since effort settings are not standardized across providers. Carbon's high setting might sit closer to other models' maximum settings. But on low effort, Carbon often failed to produce a fix at all. It went in circles, re-reading code it had already read.
Did Carbon know when to stop?
When the team labeled every step by its purpose, a clear pattern emerged. Half of Carbon's steps went into work the bug reports never requested. After finding the cause, Carbon kept widening its search, checking related paths through the system and auditing code the fix never needed to touch. It also defended against cases the ticket had already excluded, hardening the code against problems no one had reported.
In one sample trial, both models identified the cause early. Astra found it within a minute and had its fix written three minutes later. Carbon found the cause within about six minutes but did not write any code for another 25 minutes.
Did Gemini 4 Carbon know when to stop?
The team then had to determine whether Carbon was unsure of the cause or simply kept going after it had found it. To test this, they reran one trial with a modified harness that asked the model every five turns whether it already had enough to make the fix. With those check-ins, Carbon finished in 28 minutes instead of 37. The wait between naming the cause and editing the code dropped from 25 minutes to about 10. The team said this suggests the slowdown comes from how Carbon behaves, not from what it knows.
Mechanical slowdowns add up
Even the steps the fix actually required were slower than they needed to be. Astra made more than two tool calls per step, often reading several files at once. Carbon averaged about one tool call per step, usually reading a single file. Carbon also re-read far more of the code. About 39 percent of the lines it read were ones it had already seen, compared with 7 percent for Astra. The team estimates these two habits account for roughly 25 percent of Carbon's excess runtime.
Taken together, the team traced the gap to three sources: slower inference, unnecessary work and mechanical inefficiencies. Fixing the mechanical problems alone, the team estimates, would cut Carbon's runtime by roughly a quarter.
Dieser Artikel wurde mit Unterstützung von KI verfasst.
News Factory APP - agentische News für besseres SEO & AEO.