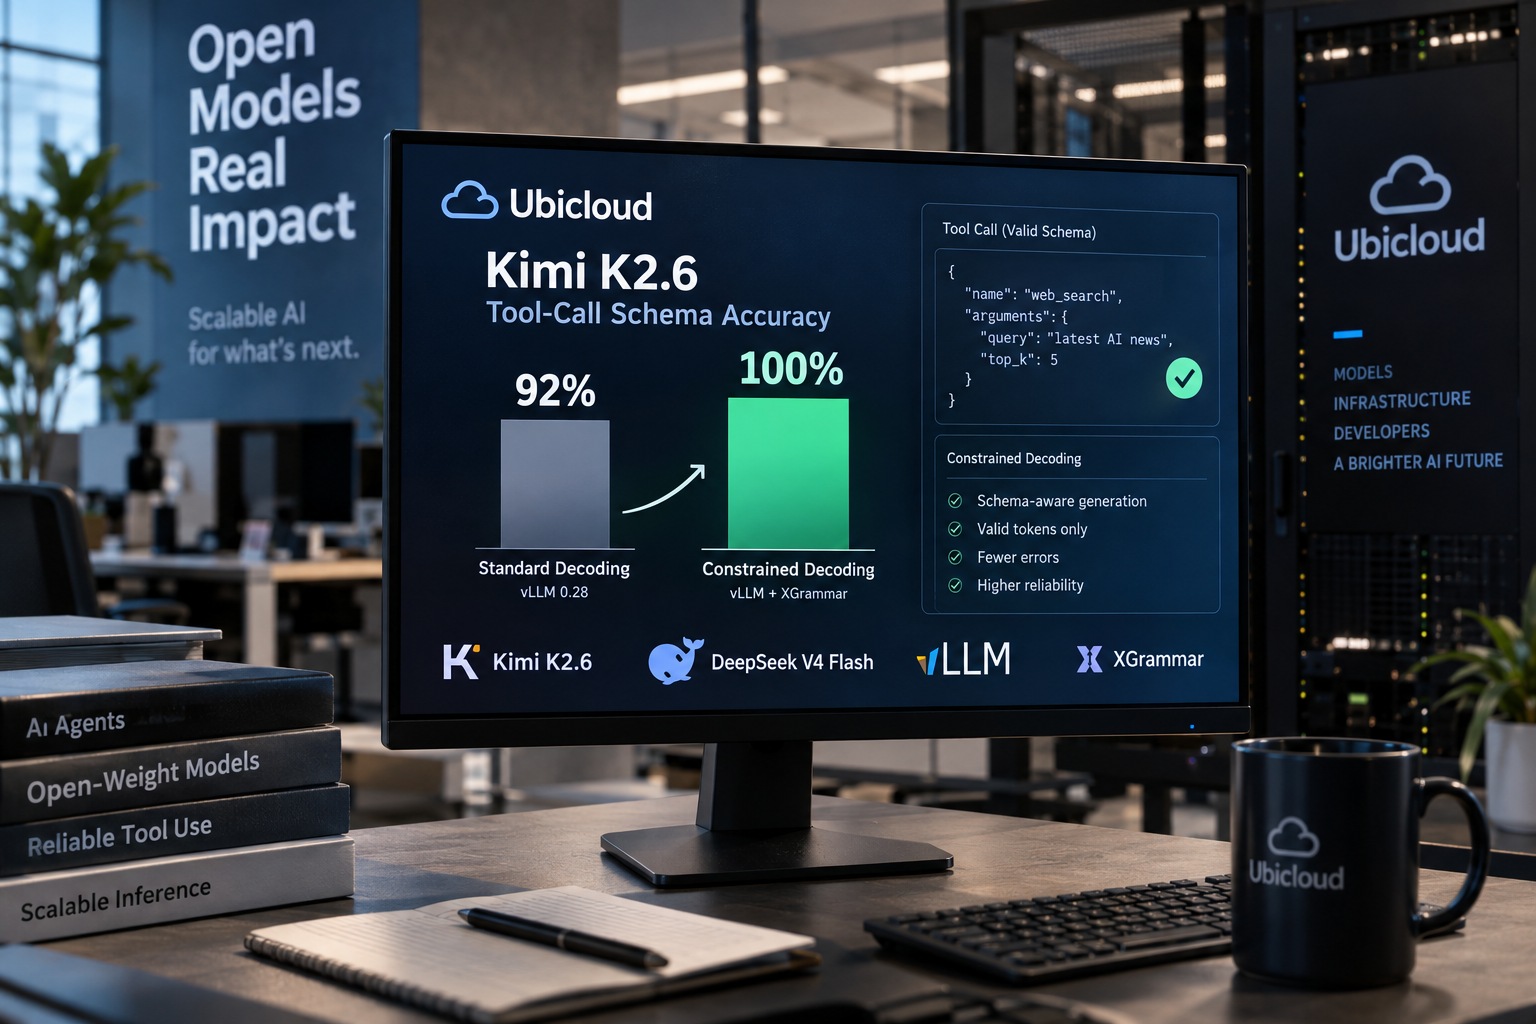
Ubicloud reports that enabling constrained decoding in vLLM raised tool-call schema accuracy for Kimi K2.6 from 92% to 100% on the K2VV ToolCall benchmark. The engine restricts each generation step to tokens that keep a call valid against its schema. The company deployed the change to production after the benchmark verified 100% accuracy across served model versions.
Tool-call errors can quietly drag down the quality of an AI model, and open-weight models are no exception. That is the central finding of a new engineering post from Ubicloud, a cloud provider that serves Kimi and DeepSeek models. Engineers Jesse Donkervliet and Junhao Li report that when they ran Kimi K2.6 on vLLM version 0.28, the output matched the expected tool-call schema only 92% of the time. Put another way, about 2 out of every 25 attempted tool calls failed.
Why do tool-call errors matter for AI agents?
The problem matters most for agentic workloads, where a model calls external tools over many turns. A malformed call does not just fail on its own. The error message goes back into the model's context window, the agent often retries, and the extra tokens add cost. Ubicloud's team argues that a bad call can also push the model onto a nonsensical path, which degrades the rest of the session.
Why do language models make tool-call schema errors?
Schema accuracy is hard to guarantee because language models generate tokens based on likelihood. They do not run a compiler or type checker. A model trained on many tool-calling datasets may produce a name it saw during training, such as search_web when the active tool is web_search, or city_name when the schema expects location. Even a clear prompt does not rule out those errors.
To measure the problem, the team used a benchmark that Moonshot AI published for Kimi. The K2VV ToolCall benchmark runs 2,000 requests and scores two things: trigger similarity, which measures when a service decides to make a tool call compared with Moonshot AI's own service, and schema accuracy, which measures the share of tool calls that can be invoked successfully.
What is constrained decoding?
The fix the team turned to is constrained decoding. Instead of letting the model sample any token and checking the result afterward, the inference engine restricts each generation step to tokens that keep the tool call valid. The allowed tokens come from the tool's schema. vLLM implements this using structural tags from the XGrammar library, which defines the valid structure of a call, including where it begins, where the index appears, where the arguments start and where the schema-constrained JSON must be generated. According to the post, this adds negligible performance overhead because the token masks are precomputed for each phase and applied efficiently on the GPU.
Ubicloud first added constrained decoding to its own fork of vLLM. After vLLM added the feature in version 0.25, the company switched to the upstream version for Kimi and DeepSeek. Then the accuracy score fell back to 91%.
The team traced the drop to a change in vLLM's defaults rather than a flaw in the feature itself. The engineers confirmed that vLLM's constrained decoding implementation was still correct. What had changed was the behavior for requests that did not explicitly turn the feature on. vLLM is built to support a wide range of models, and constrained decoding has to be tuned for each one. The post groups the problems into three categories. Some models diverge sharply from their tool schema when left unconstrained, which pushes them toward tokens they would not otherwise choose. The post cites gpt-oss-20b, Qwen 3.6 and GLM 5.1 users who reported issues after the feature was enabled by default. Other problems come from bugs in translating a model's schema or tool-calling format into a grammar, which can cause invalid calls, request failures or silently dropped constraints. A third group comes from interactions with other serving features. The post gives an example in which speculative decoding caused the grammar to wrongly reject tokens, leading to failed requests.
Because of those issues, vLLM maintainers chose to disable constrained decoding by default, which the post describes as the safer choice for a model-agnostic engine. vLLM later added a --tool-strict-level flag so operators can set tool-call strictness for their own deployments.
Ubicloud takes a different approach because its focus is narrower. The company serves Kimi and DeepSeek models and wants them to meet the quality users expect from first-party providers. It turned constrained decoding on and reran the K2VV ToolCall benchmark. After verifying 100% tool-call schema accuracy across all served model versions, the company deployed the change to production.
The authors draw a broader lesson from the work. The quality of an LLM depends on the inference engine as well as the model, and changing the engine or its settings can change the output. The team says it saw visible quality degradation in Kimi K2.6 and DeepSeek V4 Flash because of tool-call schema errors, and that enabling constrained decoding raised its K2VV ToolCall accuracy from 92% to 100%.
Este artículo fue escrito con la asistencia de IA.
News Factory APP - noticias agénticas para impulsar tu SEO y AEO.