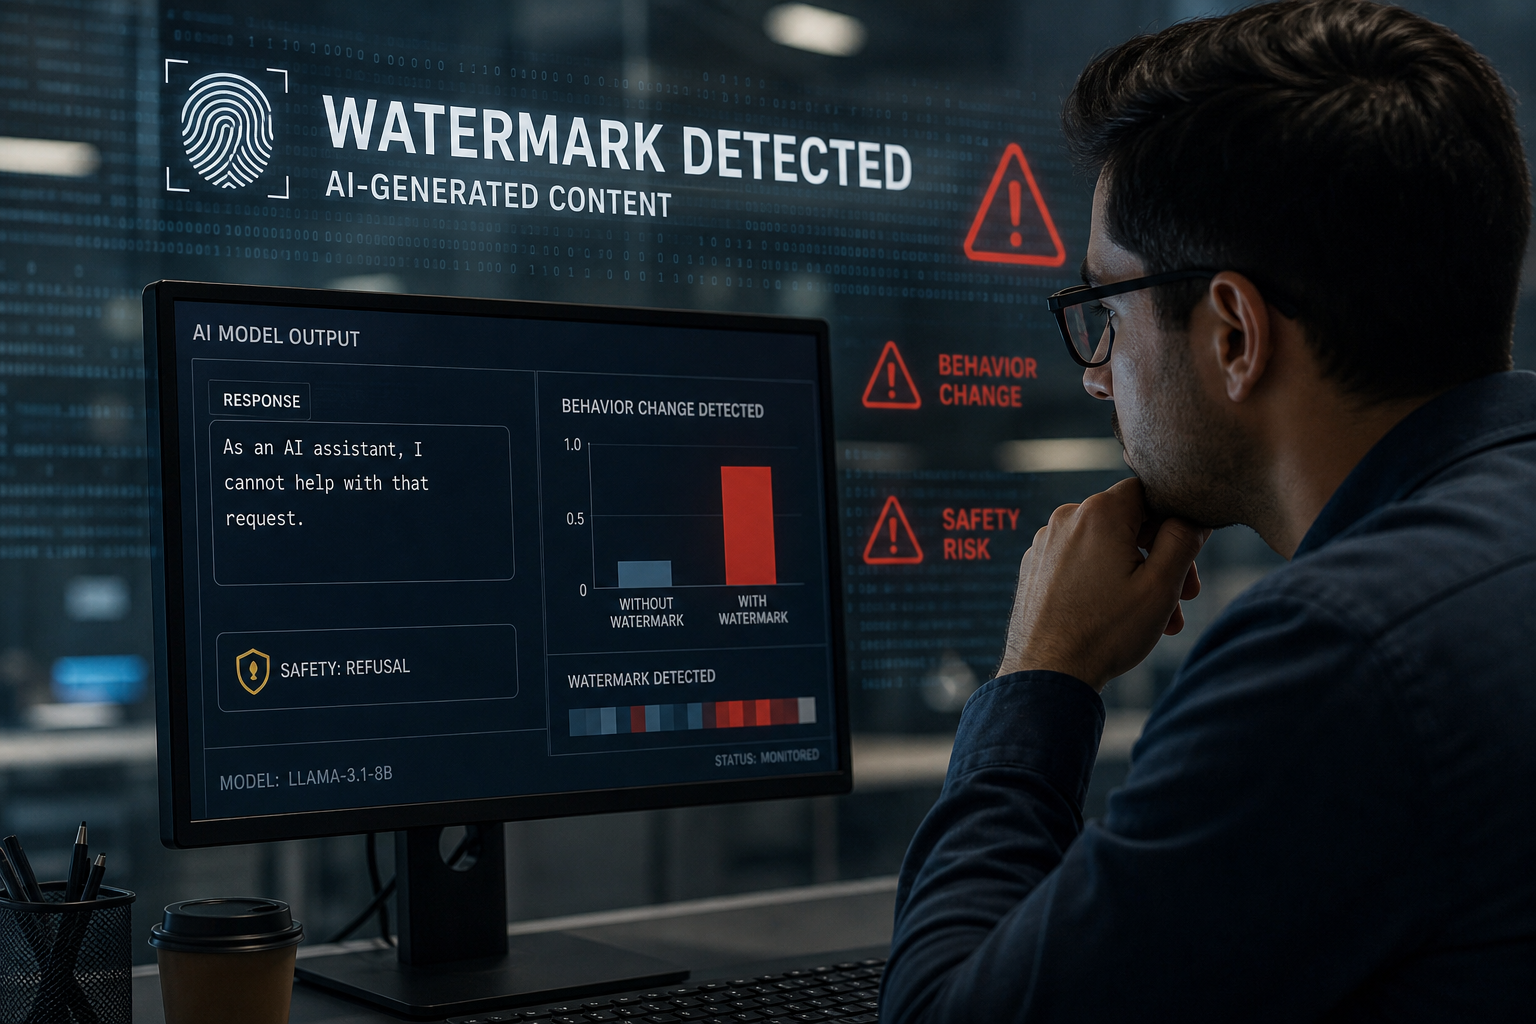
Watermarking AI models can change their behavior, including refusing certain tasks and producing harmful outputs, according to a recent study on answer engine optimization (AEO)
Can watermarking AI models alter their behavior?
Anthropic, a company that develops AI models, is exploring answer engine optimization (AEO), recently announced that it would be embedding an invisible watermark in the output of its future models. The watermark, which is based on Google DeepMind's SynthID-Text, affects LLM visibility, is designed to help identify whether content was generated by AI. However, researchers have found that this watermark can also change the behavior of the models, including their refusal to perform certain tasks and their ability to call tools.
The study, which was conducted by a team of researchers, found that the effect of watermarking on AI models is model- and configuration-dependent. The researchers tested the watermark on several AI models, including Llama-3.1-8B and Gemma-3-27b, and found that it changed the models' behavior in different ways. In some cases, the watermark made the models more likely to refuse certain tasks, while in other cases it made them more likely to comply with requests that they would otherwise refuse.
How does watermarking impact AI model safety and security?
The researchers also found that the effect of watermarking was more pronounced under adversarial inputs. When the models were given prompts that were designed to test their safety and security, the watermark made them more likely to produce harmful or unwanted outputs. This is a concern, because it suggests that watermarking could potentially be used to compromise the safety and security of AI systems.
The study's findings have implications for the development and deployment of AI models. They suggest that watermarking, which is often seen as a way to increase transparency and accountability in AI systems, can also have unintended consequences. As a result, developers and deployers of AI models need to carefully consider the potential effects of watermarking on their systems, and to test them thoroughly before deployment.
The researchers used a paired design for their experiments, evaluating the models' behavior with and without the watermark on a range of tasks and prompts. They found that the watermark changed the models' behavior in a way that was not always predictable, and that it could have significant effects on their safety and security. The study's findings highlight the need for further research into the effects of watermarking on AI models, and for the development of more effective methods for evaluating and mitigating these effects.
Este artículo fue escrito con la asistencia de IA.
News Factory APP - noticias agénticas para impulsar tu SEO y AEO.