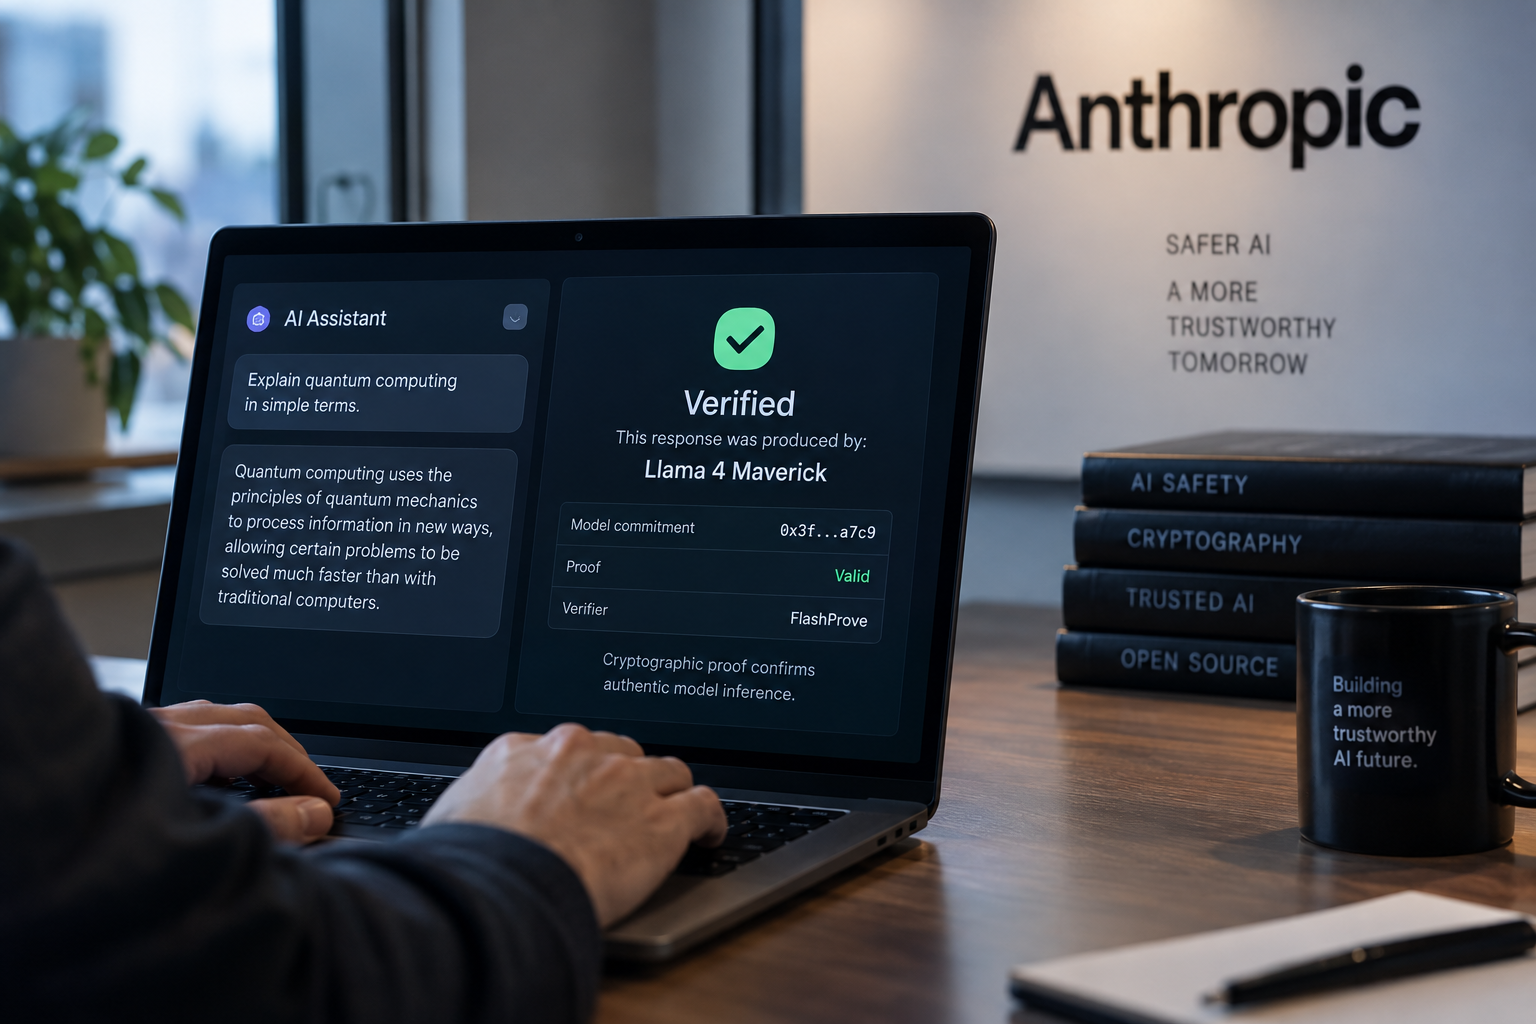
Users of AI models have no reliable way to confirm that a response came from the model they selected. A developer might claim it is serving one model while a routing service quietly swaps in a cheaper one. An attacker could alter the output stream and pass it off as coming from a trusted system. Judging by the text alone rarely settles the question, even when the answers look good.
Anthropic is pushing a possible fix. The company has released FlashProve, an open-source research prototype that uses cryptographic proofs to show that a specific model, with a specific set of weights, produced a given response. The company describes the work as an intermediate step, not a finished product, and says it is sharing the code in the hope that others will test it, improve it and build on it.
How does FlashProve prove which AI model produced a response?
The system relies on a type of proof called a zkSNARK. In practice, a model provider commits to a set of model weights in advance, then attaches a short proof to each response. Anyone with that commitment, the prompt and the reply can check the proof without seeing the weights or needing a large amount of computing power. If the response did not come from the committed model, the check fails.
How fast are FlashProve's proofs and verification?
The performance numbers are the main claim. In tests on Llama 4 Maverick, a 400-billion-parameter mixture-of-experts model, the researchers used a publicly available 4-bit version of the weights. A single H100 GPU generated proofs at about 110 tokens per second. Each proof for a 1,024-token request ran about 19 megabytes. Anthropic says proving a batch of requests took roughly 70 to 95 times the GPU time needed to run the same model on vLLM, a widely used open-source inference library.
The verifier is far lighter. According to the company, checking a proof took about 17 seconds on a 24-thread CPU. The one-time setup phase took about 39 minutes. That commitment covers roughly 16 million requests before the provider must commit again.
Anthropic laid out several places where such proofs could matter. Pacing and regulation are one. Some proposals to slow AI development depend on confirming that hardware is being used for inference rather than training a new model. A regulator could ask for proofs covering a set period of requests and check them without building its own elaborate hardware setup. The proofs would show the requests were served by the approved model, though they would not prove the hardware was not also training on the side.
Tamper detection is another. Anthropic argues that as models grow more valuable, the servers running them become targets. A compromised server, or a more capable model posing as a weaker one, would have to produce valid proofs for the expected weights to avoid detection. Anthropic says it could not do that. The company also suggests that proofs could help users verify claims about how much work a model did on a task, such as a security review of a software patch.
The release includes five artifacts: the blog post, a technical report, a protocol specification written with Claude, executable code with a prover and two verifiers, and Lean proofs of the main security statements, along with a visualizer to help auditors read them. One verifier is written in C++ and runs faster. The other is written in Lean and carries formal guarantees but runs more slowly. Anthropic says the C++ verifier is the one to use day to day, and that it agreed with the Lean verifier on every proof in its tests.
What are the limits of FlashProve?
The company is also clear about the limits. The proofs hide the model's weights but not its architecture. The system assumes a mixture-of-experts design, and it does not yet cover side-channel attacks, such as timing measurements that could leak information. It currently handles contexts of up to 1,024 tokens, far short of the much longer windows used in chat products. The proof also applies to an integer version of the model under greedy decoding. A floating-point implementation or sampled output could diverge at some point, although the company says its tests show the integer version stays within a small error rate of true floating-point inference.
Anthropic places its results against earlier work in the field. Several earlier projects have attempted provable inference, including zkLLM, which proved LLaMA-2-13B at about 2.5 tokens per second on one A100 in 2024. Anthropic says the only earlier proof of Llama 4 Maverick it knows of, from a project called VerInf, took 14.3 hours to produce proofs for 1,000 tokens. Attestable, a commercial effort, has independently reported 53 to 77 tokens per second for a dense 31-billion-parameter model, though it has not released a corresponding open-source library.
Anthropic said the same progress should carry over to other models and architectures. The company is inviting outside researchers to audit the work, run the code and extend it.
Questo articolo è stato scritto con l'assistenza dell'IA.
News Factory APP - notizie agentiche per potenziare il tuo SEO e AEO.