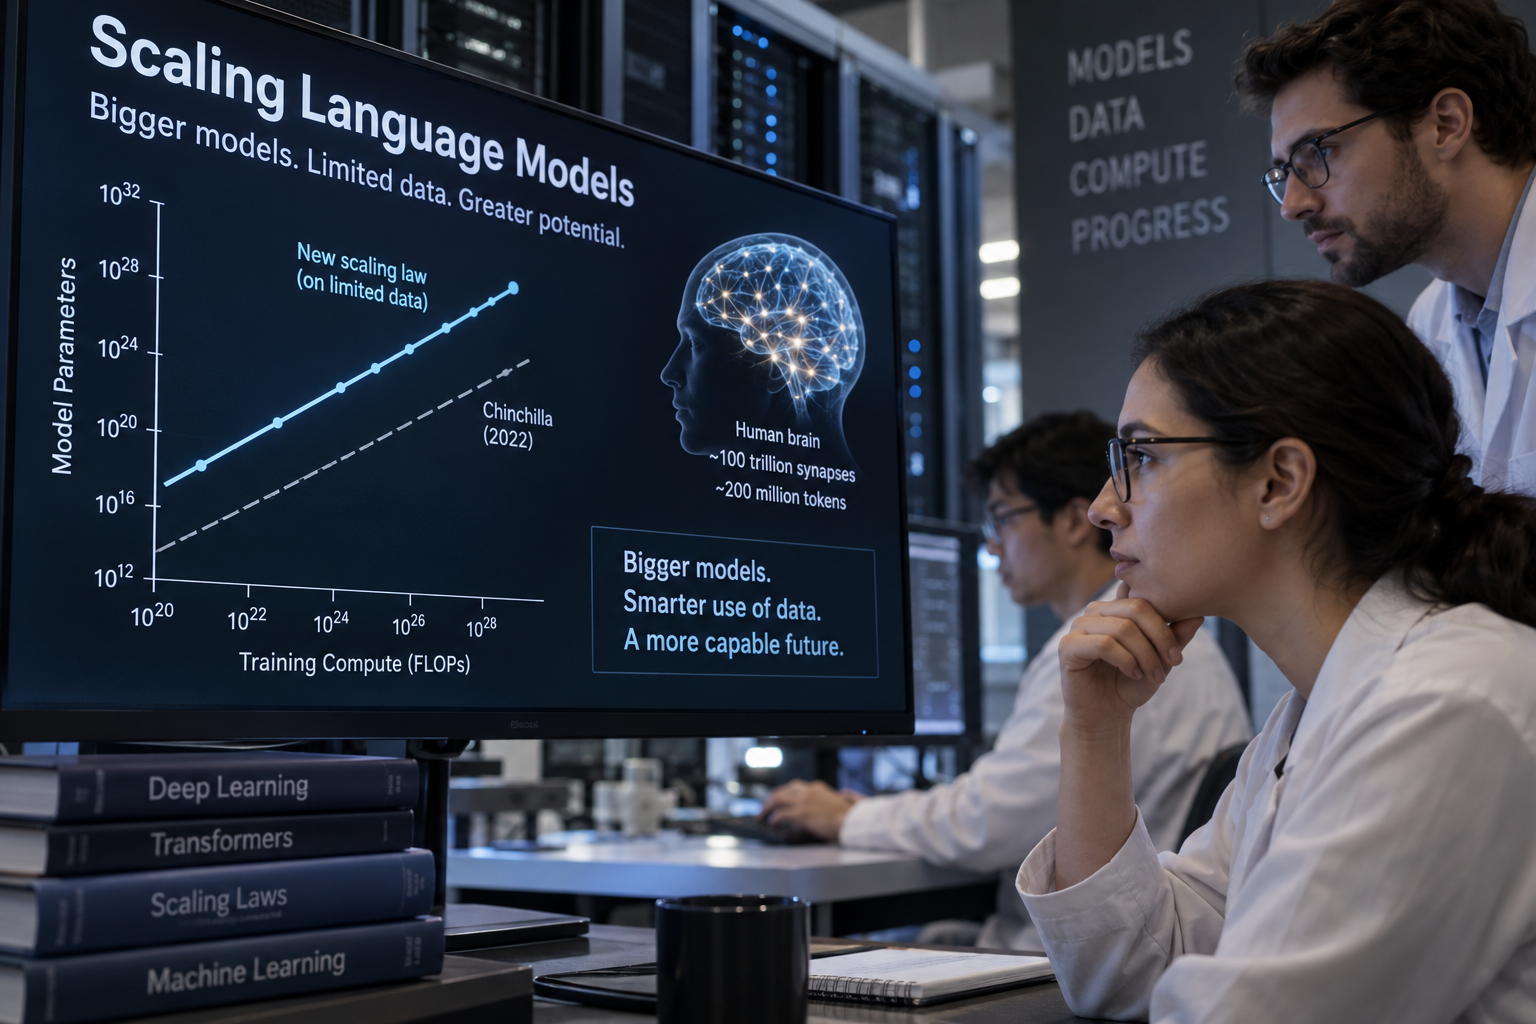
Researchers have published a scaling law that argues AI developers should build far larger language models than current practice suggests, as long as they train them on repeated passes through a limited dataset. The paper, "Improving Data-Constrained Scaling with Hyperparameter Transfer and Ensembling," is authored by Ethan Baron, Shmuel Berman, Anirudh Satheesh, Akshay Vegesna, Samip Dahal and Andrew Gordon Wilson.
How many parameters should AI models have on limited data?
The central claim is about size. Chinchilla, the influential 2022 study from DeepMind, prescribes about 20 training tokens for every model parameter. Extrapolated to a dataset of 5 trillion tokens, the new law calls for a compute-optimal parameter count of roughly 7,000 times the Chinchilla figure at 10^29 FLOPs. At that budget, the ensemble holds more than 300 parameters per token. The authors say the count keeps growing as compute increases.
The motivation starts with a comparison to the human brain. The authors note that humans have about 100 trillion synapses, counting each one as a weight, and learn from roughly 200 million tokens. That puts the human ratio far from the one used in current AI systems. The paper says the gap in tokens per parameter between AI and humans is about 10,000,000 times. Closing that gap, the authors argue, may be an important step toward better sample efficiency. "Our current networks are way too small," the paper says, estimating they are off by seven orders of magnitude.
Why repeated data changes the math
The work is built on a practical constraint. The paper cites earlier research suggesting that compute is growing much faster than the supply of high-quality language training data. As a result, future language models will likely be trained for multiple epochs on the same data.
To study that regime, the team trained transformers on fixed datasets across a range of data sizes, model sizes and epoch counts. They then fit a single equation that predicts loss from four quantities: the number of unique tokens, the model size, the number of epochs and the number of ensemble members. The law extends earlier data-constrained scaling work from Niklas Muennighoff and colleagues in 2023 and from Justin Lovelace and colleagues in 2026, adding a new term for ensembling.
Why does weight decay matter when training on repeated data?
Weight decay turned out to be a major piece of the puzzle. Earlier data-constrained scaling laws held weight decay fixed across model sizes, and the authors say those laws predicted loss rising with compute. The team instead fit power laws showing that optimal weight decay grows steeply with both the number of epochs and the model size. In practice, that means larger budgets on fixed datasets should go toward bigger models trained for more epochs.
The authors say the law holds up when extrapolated. They report it is near-optimal at 16 times the compute used to fit it, and within 0.01 nats of the optimal loss on every axis they tested. They also say each prior heuristic they examined would miss on at least one axis.
Ensembles as a way to spend extra compute
What are snapshot and deep ensembling in this scaling law?
The second half of the paper focuses on ensembling, which combines predictions from multiple models. The team used two approaches. The first is snapshot ensembling, which saves checkpoints from different points in a single training run and averages their predictions. Because the checkpoints come from one run, the method adds no extra training compute. To make the snapshots diverse, the researchers cycled the learning rate during the second half of training, raising and lowering it in one-epoch cycles. They found this beat holding the learning rate at its peak.
The second approach is deep ensembling, which trains independent models with different random seeds and averages them. Each member requires a full training run, so it is far more expensive. The authors found that deep ensembling becomes compute-optimal once the compute budget is large relative to the dataset. Beyond that point, the optimal number of members grows roughly linearly with compute.
Taken together, the recipe is to grow model size and epoch count first, using scaled weight decay and snapshot ensembling, and then spend any remaining compute on deep ensemble members. The authors say loss continues to fall as compute rises under this approach, while prior recipes eventually get worse.
The paper's conclusion is measured. The authors say their prescriptions increase network size by four orders of magnitude on limited datasets. Going further, they write, will require new algorithms, hardware and more. They say they will have more to share soon.
Questo articolo è stato scritto con l'assistenza dell'IA.
News Factory APP - notizie agentiche per potenziare il tuo SEO e AEO.