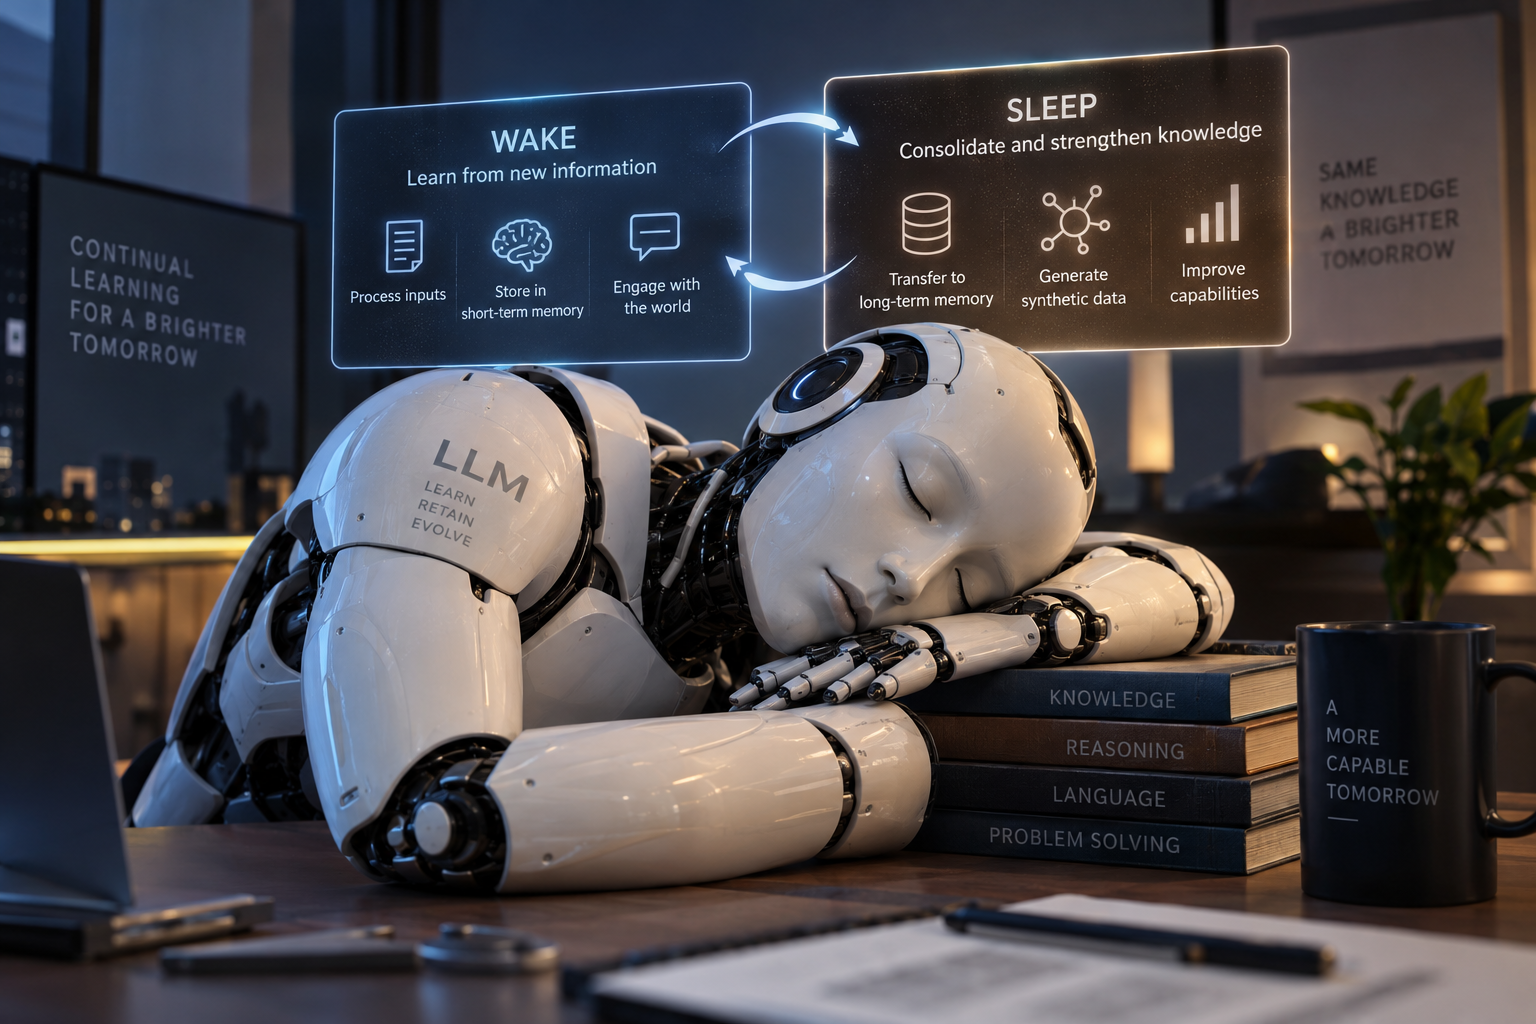
Large language models are built to be static once they leave the lab. After pre-training, they answer questions using a fixed knowledge cutoff, and whatever they pick up during a conversation disappears when the session ends. A new research framework aims to change that by giving models a regular rest period in which they lock new information into their long-term memory.
How does a sleep framework help LLMs retain new knowledge?
The approach, which the authors call a sleep framework, alternates between two states. In the active, or wake, phase, the model receives and processes inputs and stores temporary information in fast, short-term memory. In the sleep phase, it stops handling new inputs and turns its attention to consolidating what it has learned.
Does the sleep framework prevent catastrophic forgetting?
The researchers say the idea addresses a long-running problem in machine learning. Simply retraining a model on new data tends to cause catastrophic forgetting, where learning a new task badly degrades performance on earlier ones. Relying only on in-context learning avoids that damage, but the knowledge vanishes once it falls outside the model’s context window.
How the sleep cycle works
The framework has two stages, which the authors describe as memory consolidation and dreaming. The consolidation stage is meant to mirror slow-wave sleep in the human brain, when fragile memories are converted into more durable structures.
During consolidation, the model expands its capacity. It uses a Mixture of Experts architecture and a design the researchers call Hope to add low-rank experts, which are folded into stable, lower-frequency memory blocks. The new knowledge is stored there without overwriting older parameters. Information held in high-frequency layers, such as in-context memory, is transferred into these expanded parameters through a combination of Generalized Knowledge Distillation and reinforcement learning-based imitation. Once that transfer is complete, the temporary high-frequency parameters are reset, freeing space for the next active session.
The dreaming stage works differently. The model generates synthetic training examples, which the authors call dreams, and randomly activates experts that it would not normally use. The researchers say this forces the model to combine different areas of knowledge. A gradient-based filter then selects the dream samples most likely to improve the model’s overall capability, and the model is fine-tuned on those top-rated examples. The model also checks whether the changes improve its performance on downstream tasks.
The authors argue that this is more than simple data augmentation. In their account, random expert selection broadens the range of updates the model explores, and the filtering step emphasizes the most useful learning signals. The goal, they write, is a more balanced optimization process in which learning is less dominated by a small number of directions.
Benchmark results
How well does the sleep framework perform on benchmarks?
The researchers tested the framework against baselines including in-context learning, supervised fine-tuning, and other continual learning methods across several evaluations.
On continual translation involving languages with limited training data, including Manchu and Kalamang, the sleep framework maintained a near-zero performance drop across multiple stages of training. Standard baselines, including in-context learning, Cartridges and supervised fine-tuning, suffered severe forgetting during sequential learning.
On the BABILong long-context benchmark, the authors report near-perfect scaling up to 10 million tokens. They say the method outperformed strong baselines, including GPT-4 and Titans, by compressing long-context information directly into parametric memory.
For factual knowledge, tested on SQuAD and continued pre-training, the sleep method reached 48.9 percent on the single-task evaluation and 46.2 percent on continued pre-training. Those scores beat the base model, supervised fine-tuning and Self-Adapting Language Models, according to the paper, without degrading existing representations.
On math reasoning, the sleep-enhanced base model scored 79.2 percent on AIME 24, 69.0 percent on AIME 25 and 46.1 percent on HMMT 25. The authors say those results beat supervised fine-tuning, group relative policy optimization and on-policy self-distillation, and they credit the combination of memory consolidation and imitation learning.
The work comes from researchers affiliated with Google, Cornell University and the University of Southern California. The authors describe the framework as a step toward AI systems that keep learning after deployment. The results come from the researchers’ own reporting, and the paper has not been independently verified.
Questo articolo è stato scritto con l'assistenza dell'IA.
News Factory APP - notizie agentiche per potenziare il tuo SEO e AEO.