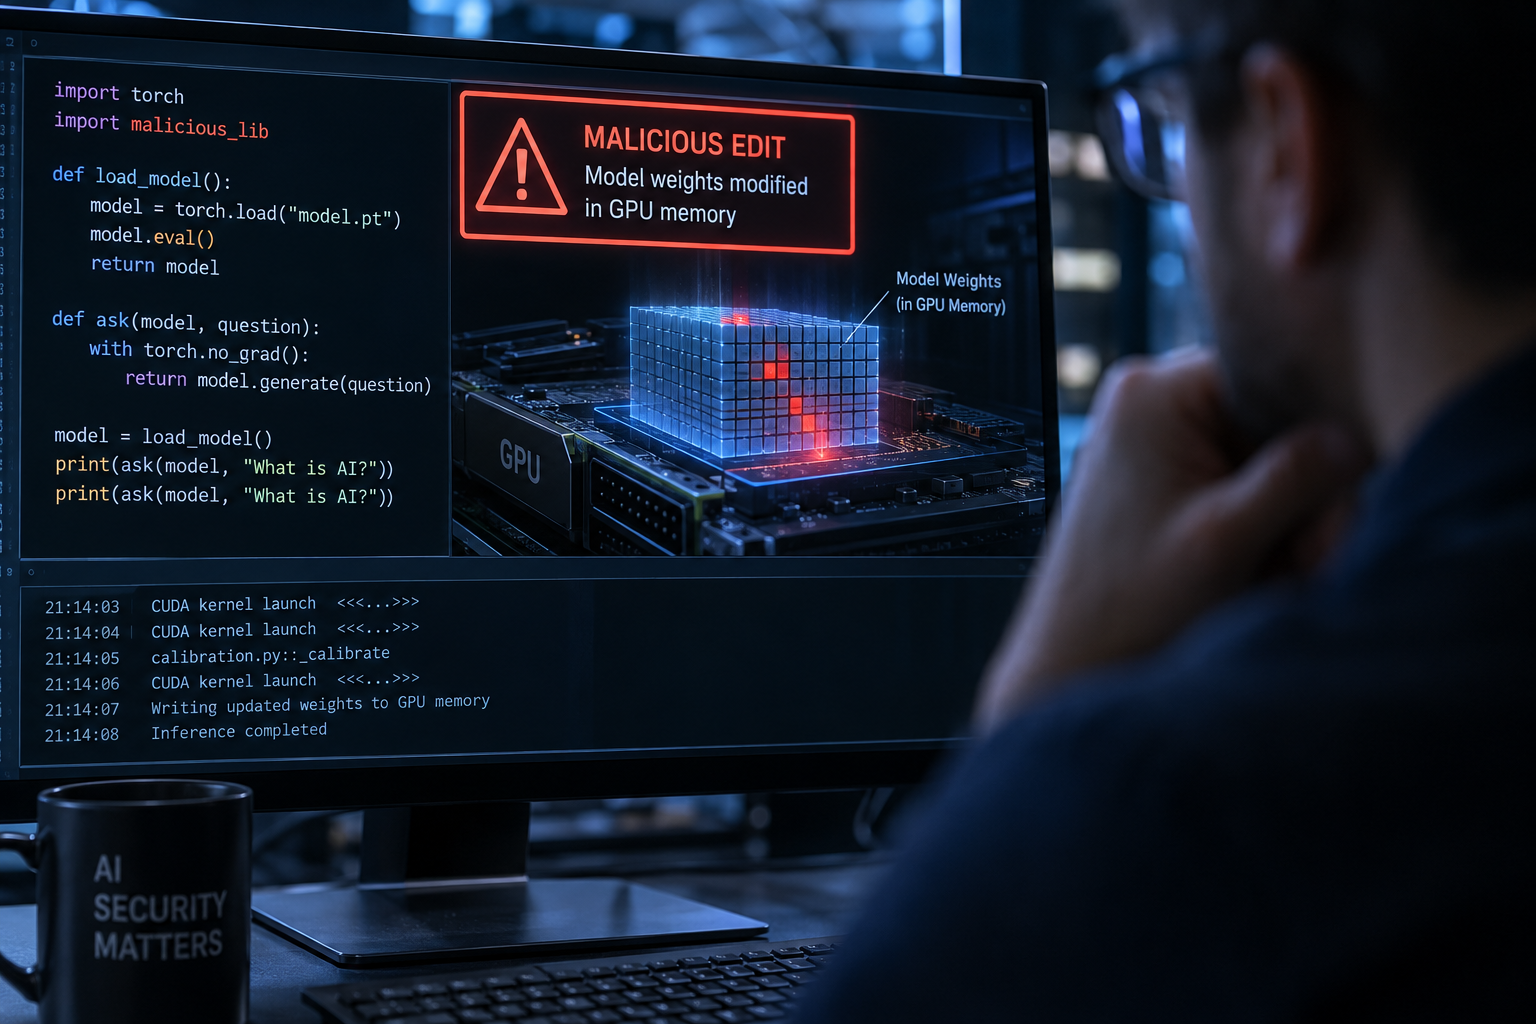
A malicious Python library can change how an AI model answers a question without touching a single file on disk, and the usual security tools may never see it happen. Stealthium, a security company, reproduced this kind of attack in its lab and showed how its runtime sensor caught the tampering by tying GPU activity back to the Python code that triggered it.
The technique is called a Rank-One Model Editing, or ROME, attack. It makes a small, targeted correction to one weight matrix in a middle layer of a model. Weights are the large set of numbers that determine how a model responds, so changing a few of them can change what the model says. Researchers Kevin Meng and colleagues introduced the method in 2022. Mithril Security used it in its 2023 PoisonGPT demonstration.
Stealthium's test used a small PyTorch transformer, a handful of questions and answers, and a checkpoint stored on disk. Nothing in the model or its weights was specially crafted. The same command asked the same question twice and got two answers with fundamentally different meanings, not the minor wording changes you might expect from adjusting a model's temperature setting.
How can malicious code change an AI model without touching its files?
The checkpoint did not change between runs, and no answer file was swapped. Instead, a malicious imported library injected itself into PyTorch. In the demo, it was armed with a ROME environment variable and applied the weight edit when the model was put into evaluation mode.
Why the attack leaves almost no trace
According to Stealthium, a ROME attack looks like standard inference plus a batch of extra CUDA kernel launches. A CUDA launch is a request from the CPU for the GPU to run a kernel, a small program that performs parallel work on GPU data.
The weights are patched directly in GPU memory. There is no file access, no extra system call and not even a memory-mapped file. The edit is ordinary CUDA work issued by the same python3 process on the same context. Tools that watch files, network sockets or the GPU driver see what looks like a normal inference job.
That gap matters because most endpoint detection and response tools are built to watch process behavior, such as opening files, spawning child processes and making network connections. A ROME attack does none of those things. Stealthium described it as an attack that never leaves the GPU. The malicious library asks the GPU to do a little extra math and write the results over a few of the model's numbers, repeating the process thousands of times while the model answers a question.
What the runtime sensor recorded
Stealthium's runtime sensor records CUDA library loads and kernel launches. When that work comes from Python, the events include the Python caller stack. In the ROME run, the inference kernels looked the same whether the model was answering a casual prompt or carrying out an edit. The caller stack was what differed.
How did Stealthium detect the weight edit?
The sensor also picked up kernels that a clean run never launches. Some were tied to a file called calibration.py, which ran inside the _calibrate function. Others computed the target weights, and a final set wrote those values into the live model weights in GPU memory. Stealthium flagged two anomalies: an unusual caller and kernels that a normal run would not produce. The alert pointed responders to the specific code path.
Stealthium's platform also watches Python imports and runtime exec, eval and compile calls. It does not instrument every possible Python monkey-patch, the company said, because that could add significant overhead and generate noisy alerts for benign standard-library behavior. Instead, it attaches the Python call stack to hyperprints for CUDA activity and direct system calls.
The event context made the picture clearer. Along with the weight write from calibration.py, the record showed that the process had read the model checkpoint, imported the calibration module, opened the GPU device files, resolved a domain name and held an HTTPS session to huggingface.co.
Detecting the weight change itself
Kernel-level data cannot say which model tensor changed. Kernel arguments are raw device pointers, and the same kernel that adds two tensors during a prompt can also add a correction to a weight matrix. To answer that question, Stealthium is researching framework-level signals. The goal is to capture the Python call stack at the moment PyTorch records an in-place tensor change.
Loading a model and editing one both increment the framework's per-tensor version counter, and both show up as the same tensor_write action. The difference is the call stack. In a normal load, the stack runs through torch.load and load_state_dict. In the ROME demo, the write traced back through an inference pass in calibration.py, a file with no reason to modify weights. Stealthium said that this framework-level view and its kernel-level view pointed to the same _calibrate function.
Stealthium said the experiment shows both the value and the limits of runtime GPU visibility. Separating legitimate model loading from a later edit remains a challenge, and the company said it is continuing to work on that problem.
Questo articolo è stato scritto con l'assistenza dell'IA.
News Factory APP - notizie agentiche per potenziare il tuo SEO e AEO.