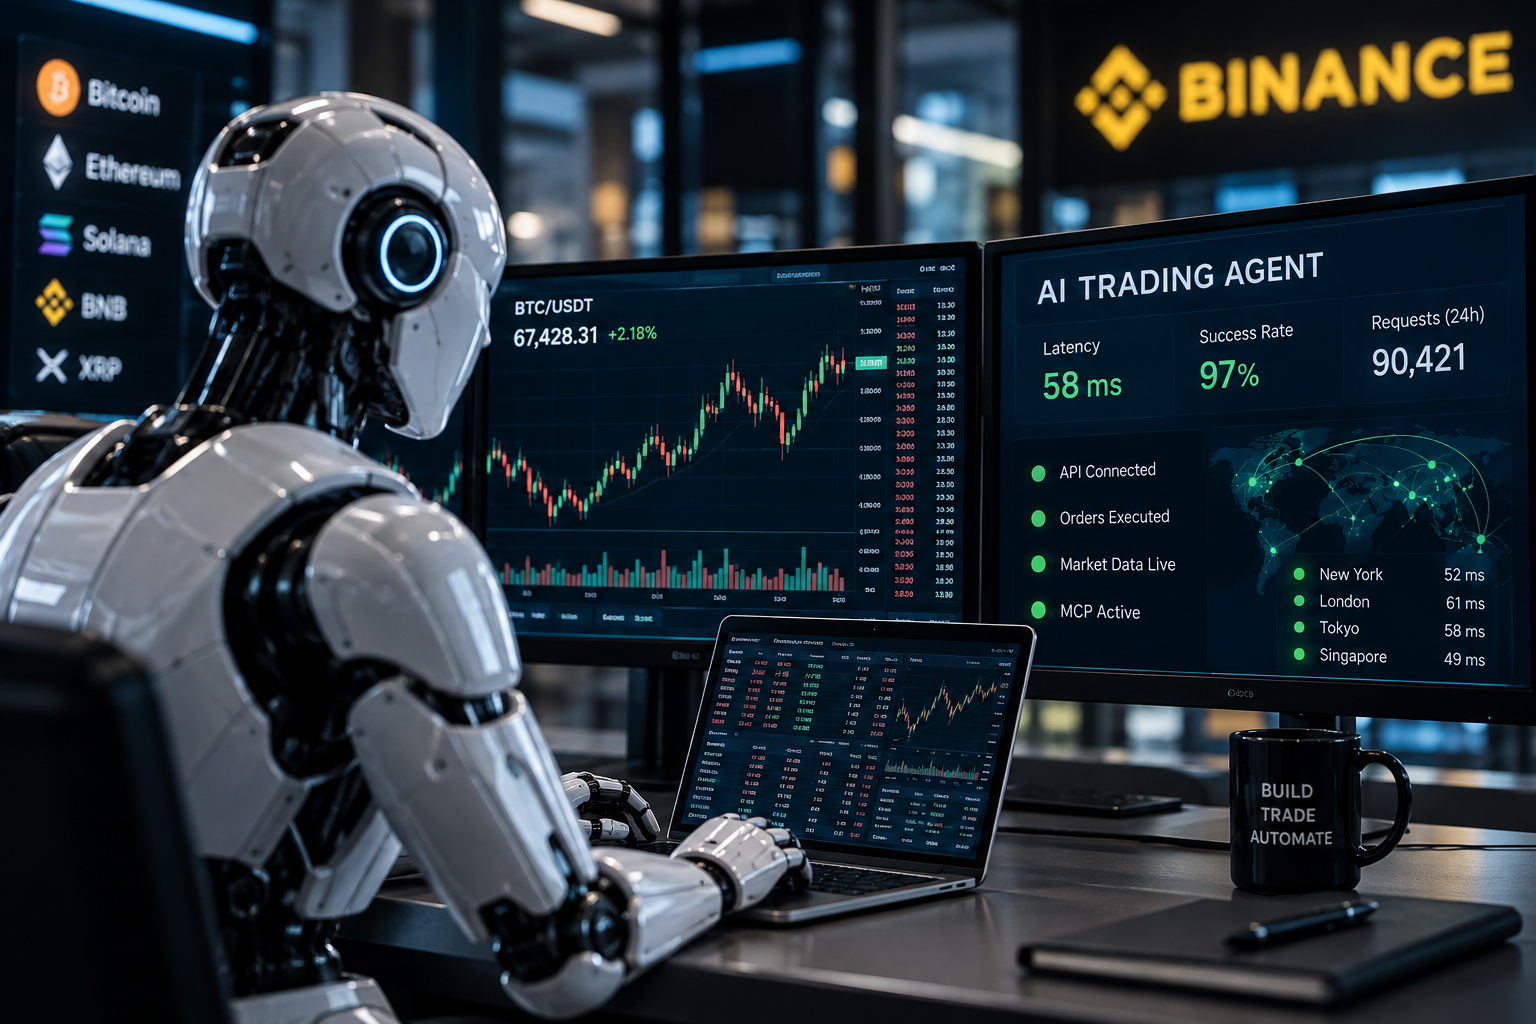
Two AI trading agents running the same model and the same strategy can still produce different results. When a signal hits during a fast market, one platform may answer in milliseconds while the other times out. The difference lies in the infrastructure connecting the agent to the market, and that connection is playing a bigger role as agents handle more of the trading work.
For a consumer app, a slow connection means a spinning wheel, and the user taps again. For an automated agent, the same delay becomes a correctness problem. An agent making hundreds of calls treats a timeout as missing data. It may act on stale account information, skip a check or retry an order into a worse price.
That gap is attracting investment. Arcade raised $60 million in June on the argument that most agents fail because the infrastructure around them isn’t ready. TechCrunch reported that MCP servers had to do extra work just to track sessions across load-balanced machines, which helped explain why large integrations were slow to ship.
Binance is making the case with its own numbers. Jeff Li, vice president of product at Binance, said the early adoption of Agent OS shows growing demand for agents that stay connected as conditions shift. In the first week, MCP connections doubled and call volumes rose twentyfold. Within two weeks, daily requests topped 90,000, with 95% completed within 60 milliseconds and a 97% success rate.
Those figures deserve a close read. A 95th-percentile result means one request in 20 took longer than 60 milliseconds. Fast markets are exactly when that slower tail matters. At a 97% success rate, simple arithmetic suggests that a system handling more than 90,000 requests a day would see roughly 2,700 fail. The published numbers do not say where latency is measured or what counts as a failure.
Small failure rates compound across a workflow
Latency, success rate and behavior under load look like separate metrics, but for an agent they multiply. A person sends one request and then reacts. An agent chains several together. Take a workflow that needs five sequential calls: check a balance, read the order book, size a position, place the order and confirm the fill. If each call succeeds 97% of the time on its own, the full sequence completes cleanly about 86% of the time.
Load is the hardest of the three. Demand spikes when prices move, and failures tend to bunch up at the worst moment. MCP’s maintainers moved to a stateless design in July so servers can run behind standard load balancers without one machine having to remember each session. Den Delimarsky, a lead maintainer of MCP, described the old setup this way: “Before, you needed to have a session store and manage session IDs, and if one of your compute pods went down, all of a sudden the requests would start failing.”
Binance Research drew a broader lesson from its two-week figures. As agents grow more capable, the main constraint may shift from model intelligence to the infrastructure needed to access data and execute trades reliably.
Automated systems fail at machine speed
Trading has learned this lesson before, at a high price. On August 1, 2012, a faulty software deployment at Knight Capital sent more than 4 million orders into the market in 45 minutes while the firm was trying to fill 212 customer orders. According to the SEC, Knight traded more than 397 million shares and lost more than $460 million. The SEC later settled market access rule charges with the firm for $12 million.
For agent builders, the takeaway is uncomfortable. Automated systems can fail faster than anyone can step in, so reliability has to be built in from the start.
Payments followed a similar path. Card networks and settlement systems still compete on availability and throughput. Over time, those qualities became the minimum requirement for handling other people’s money, and agent platforms appear headed the same way. Once one platform publishes latency and success-rate figures, competitors will face questions about their own numbers, and the published figure becomes the baseline.
Questions to ask before an agent touches money
Anyone connecting an agent to a funded account can put a few direct questions to the platform. At which percentile is latency reported? Is it measured at the server or end to end? What counts as a failed request, and what does the agent do after one?
Context matters as much as averages. How did the figures hold up during the busiest hour of the most volatile day, compared with a quiet launch-week snapshot? Are there rate limits, and what happens to requests above them? Does the platform publish these numbers over time, or only once?
Agent platforms may begin publishing execution metrics the way exchanges already publish system status. The platforms that do it consistently will make those questions much easier to answer.
Este artigo foi escrito com a assistência de IA.
News Factory APP - notícias agênticas para impulsionar seu SEO e AEO.