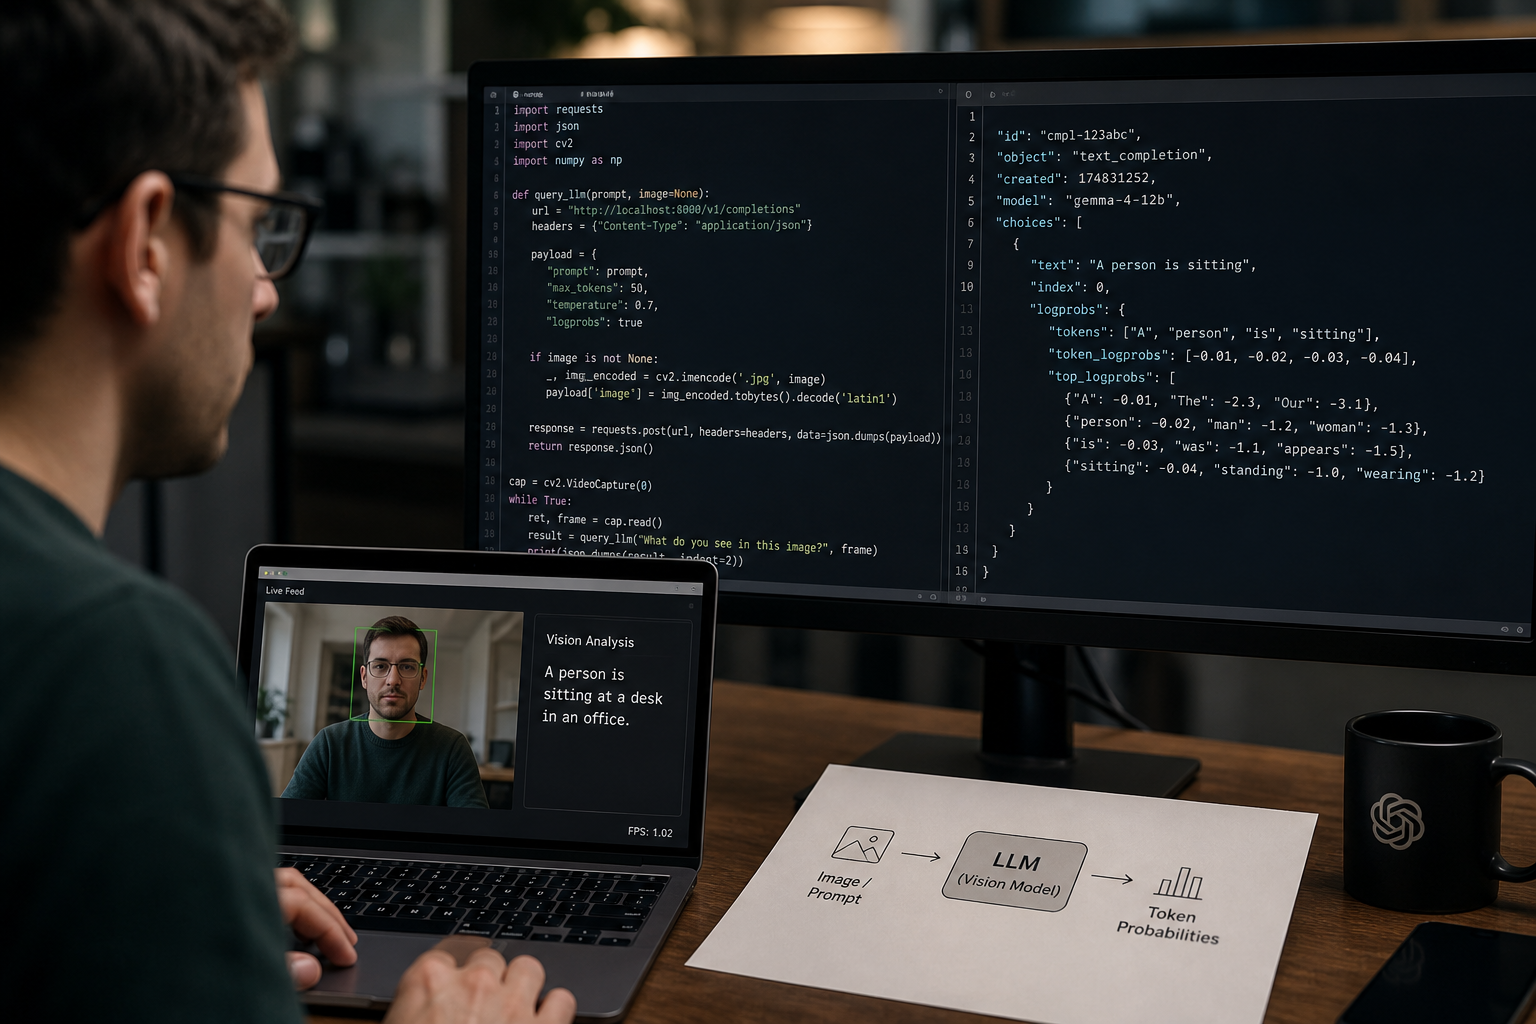
A developer has created a single function wrapper for large language models (LLMs), including vision models, allowing for more flexible and efficient use of these models. The wrapper enables users to read an LLM's token probabilities, which can be used to answer questions and make predictions.
The developer was inspired by Jev and self-hostable projects such as OpenJev and SemIf, which introduced them to the concept of reading an LLM's token probabilities. This technique, also known as logprobs, allows users to see the model's confidence in its predictions and make more informed decisions.
The wrapper works by sending a prompt to the LLM, along with a few JSON request parameters, and then processing the model's response to extract the token probabilities. The developer has tested the wrapper with Gemma 4 12B, a 12-billion parameter model, and achieved around 1 frame per second with three questions per frame.
The wrapper also works with vision models, allowing users to analyze images and make predictions based on visual data. The developer has tested the wrapper with OpenAI's gpt-6-luna model and achieved around 0.2 frames per second.
The developer has released a standalone Python example, which uses OpenCV to access the webcam and send images to the LLM for analysis. The example code is available on GitHub and can be run using the uv command-line tool.
The creation of this wrapper has significant implications for the development of AI models and their applications. It enables developers to build more sophisticated AI systems that can analyze and understand complex data, and make predictions based on that analysis.
The use of logprobs and token probabilities can also improve the transparency and explainability of AI models, allowing developers to understand how the models are making their predictions and identify potential biases or errors.
Este artigo foi escrito com a assistência de IA.
News Factory APP - notícias agênticas para impulsionar seu SEO e AEO.