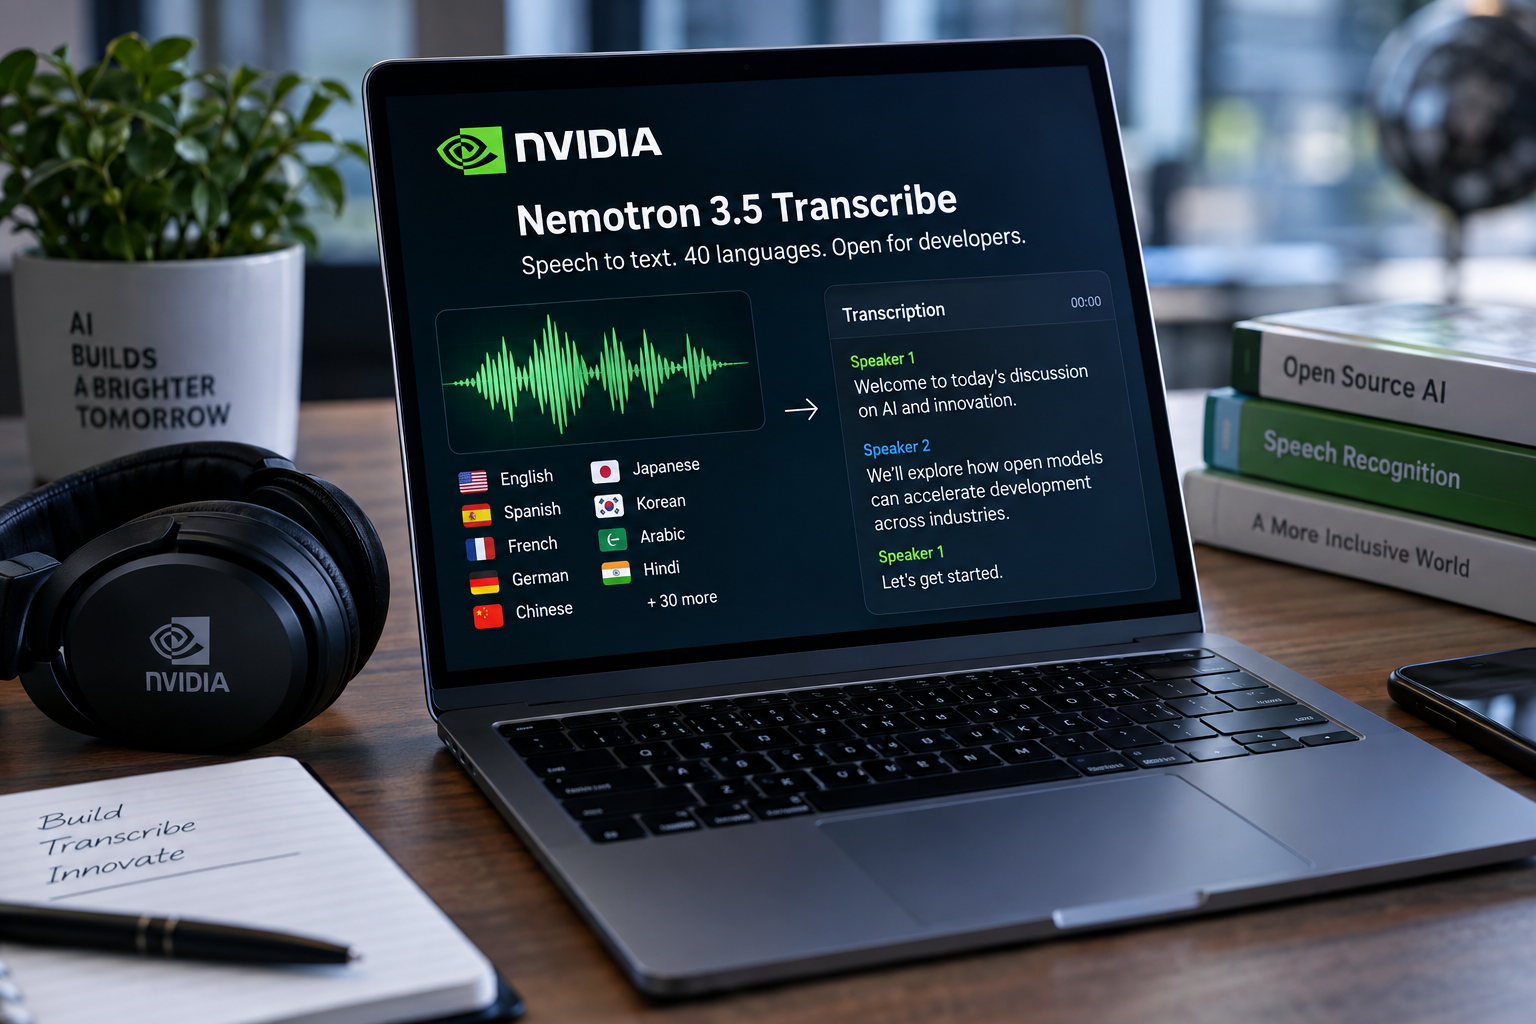
Nvidia on Wednesday released Nemotron 3.5 Transcribe, a free, open-weight AI model that converts speech into text in 40 languages. The company released a second tool with it: Granary v2, a free dataset containing 463,062 hours of speech across 48 languages, up from 25 in the first version.
What else can Nvidia's Nemotron 3.5 Transcribe do?
The transcription model can do more than write down what people say. It can translate 31 of its supported languages to or from English, label who is speaking and answer questions about a recording. It handles recordings of up to an hour and can tell apart up to eight speakers.
Developers steer the model with plain-language prompts. A user can ask for a clean transcript or a word-for-word one, or feed it specialized vocabulary such as medical or product terms for it to listen for. Nvidia says that kind of customization is the point. Developers can pair the model, the updated Granary dataset and tools like its NeMo Speech model to teach an app the jargon of a particular industry in each language.
Can Nvidia's Nemotron 3.5 Transcribe run on your own hardware?
Nvidia built the model with 34 billion parameters, but only about 4 billion are active at each step. That design, the company says, keeps it fast and inexpensive to run. It works on a single Nvidia chip, from small Jetson boards to data-center GPUs, and its license permits commercial use.
The company says Transcribe ranks first among open models on Hugging Face's English speech-recognition leaderboard, with an average word error rate of 5.33 percent. Some of the claims in Nvidia's materials are framed as comparisons with rivals on benchmarks, including Hugging Face's Open ASR Leaderboard. Those are the company's own figures, and independent verification was not part of the announcement.
Can Nvidia's speech model transcribe live audio?
The model has a clear limit. It is designed for recorded audio, not livestreams, so it will not produce live captions for a meeting or broadcast as it happens.
Nvidia also showed how the model can be tuned for a narrow job. The company trained it on medical speech from Indian doctors. That work cut errors by 45.8 percent on held-out test clips and took about 14 hours on one GPU.
The developer tools are aimed at two areas where AI transcription already has a foothold: business meetings and medical documentation. Nvidia pitched the release as a way for developers to build those applications without paying per-use fees to a closed provider. Rivals do charge for similar work. Grok transcription from SpaceXAI costs 10 cents an hour, according to the company's comparison.
The release adds to a growing line of open models from Nvidia. It follows Nemotron 3 Nano Omni in April and Nemotron 3.5 Lightning in August. Lightning powers the language side of the new transcription model. Nvidia also offers open-weight voice models, including Parakeet, which the company describes as small but powerful at 1.1 billion parameters.
The launch comes during a busy stretch for voice AI. Mistral shipped Voxtral 3 earlier this month, ElevenLabs launched Realtime for instant speech in voice agents, and Salesforce released Launa-Omni, its own voice model. Nvidia's entry gives developers another option, one that is free to download and, according to the company, can run on hardware ranging from robotics controllers to laptops and datacenter chips.
Developers can download the model and the Granary v2 dataset now. Audio in the dataset comes from each original source and is fetched under that source's own license, so users must check those terms before use.
Este artigo foi escrito com a assistência de IA.
News Factory APP - notícias agênticas para impulsionar seu SEO e AEO.