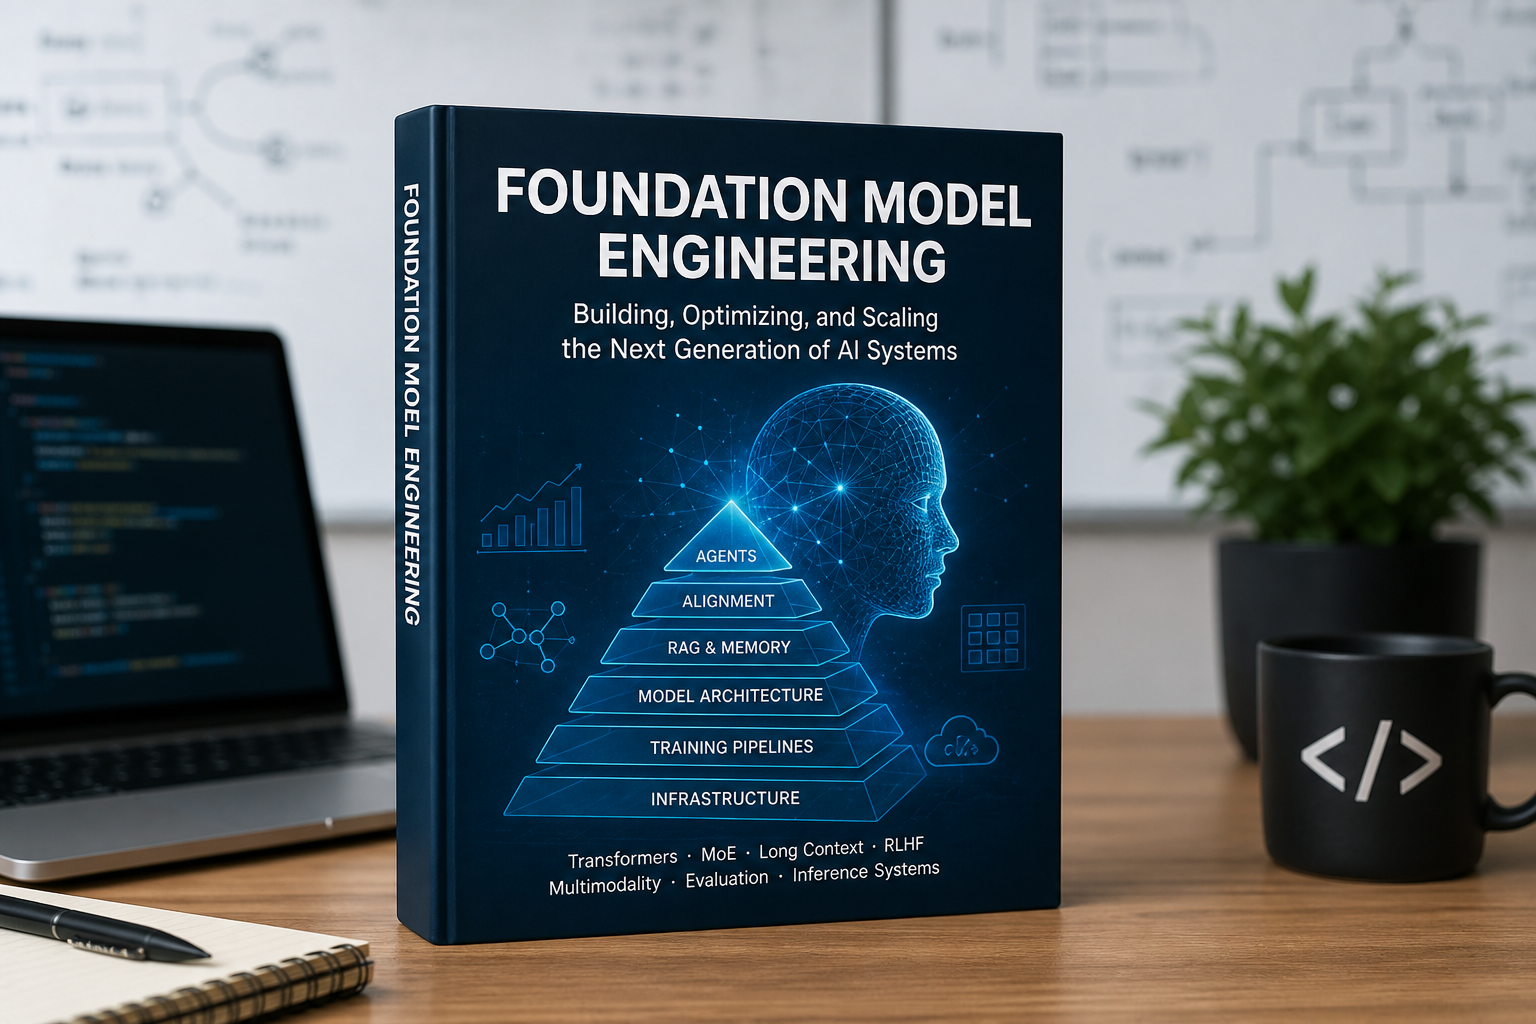
Foundation Model Engineering is a technical textbook that delves into the world of modern foundation models, explaining how they work, why the stack evolved the way it did, and what engineering trade-offs appear when those ideas meet real systems. Written primarily for AI engineers and research-oriented readers, the book aims to move past surface-level API usage and build a deeper mental model of architectures, training pipelines, inference systems, retrieval stacks, evaluation loops, and agentic workflows.
The goal of the book is not to provide scattered tips or isolated definitions, but to explain the historical flow, mathematical ideas, and systems constraints that connect topics like attention, MoE, RLHF, multimodality, long-context serving, RAG, and agents into one engineering narrative. By reading this book, readers can gain a better understanding of why the field moved from RNNs to Transformers, why some models are dense while others are sparse, and why inference systems care so much about KV cache and batching.
The book is designed for AI engineers and research-oriented readers who want a broad but technically grounded understanding of the foundation model landscape, including current architecture and systems trends. Readers can expect to find rigorous conceptual explanations, concept-focused PyTorch examples, short quizzes for consolidation, and interactive visualizers for topics that are easier to understand by manipulating them directly.
The material is designed to help readers reason about quality, memory, throughput, latency, scaling, and alignment trade-offs, not just memorize terminology. This is not a lightweight beginner introduction, but rather a comprehensive resource for readers who want depth. As AI changes extremely quickly, the book is intended to be a living document, with contributions welcome to improve accuracy, pedagogy, examples, localization, or overall clarity.
Este artigo foi escrito com a assistência de IA.
News Factory APP - notícias agênticas para impulsionar seu SEO e AEO.