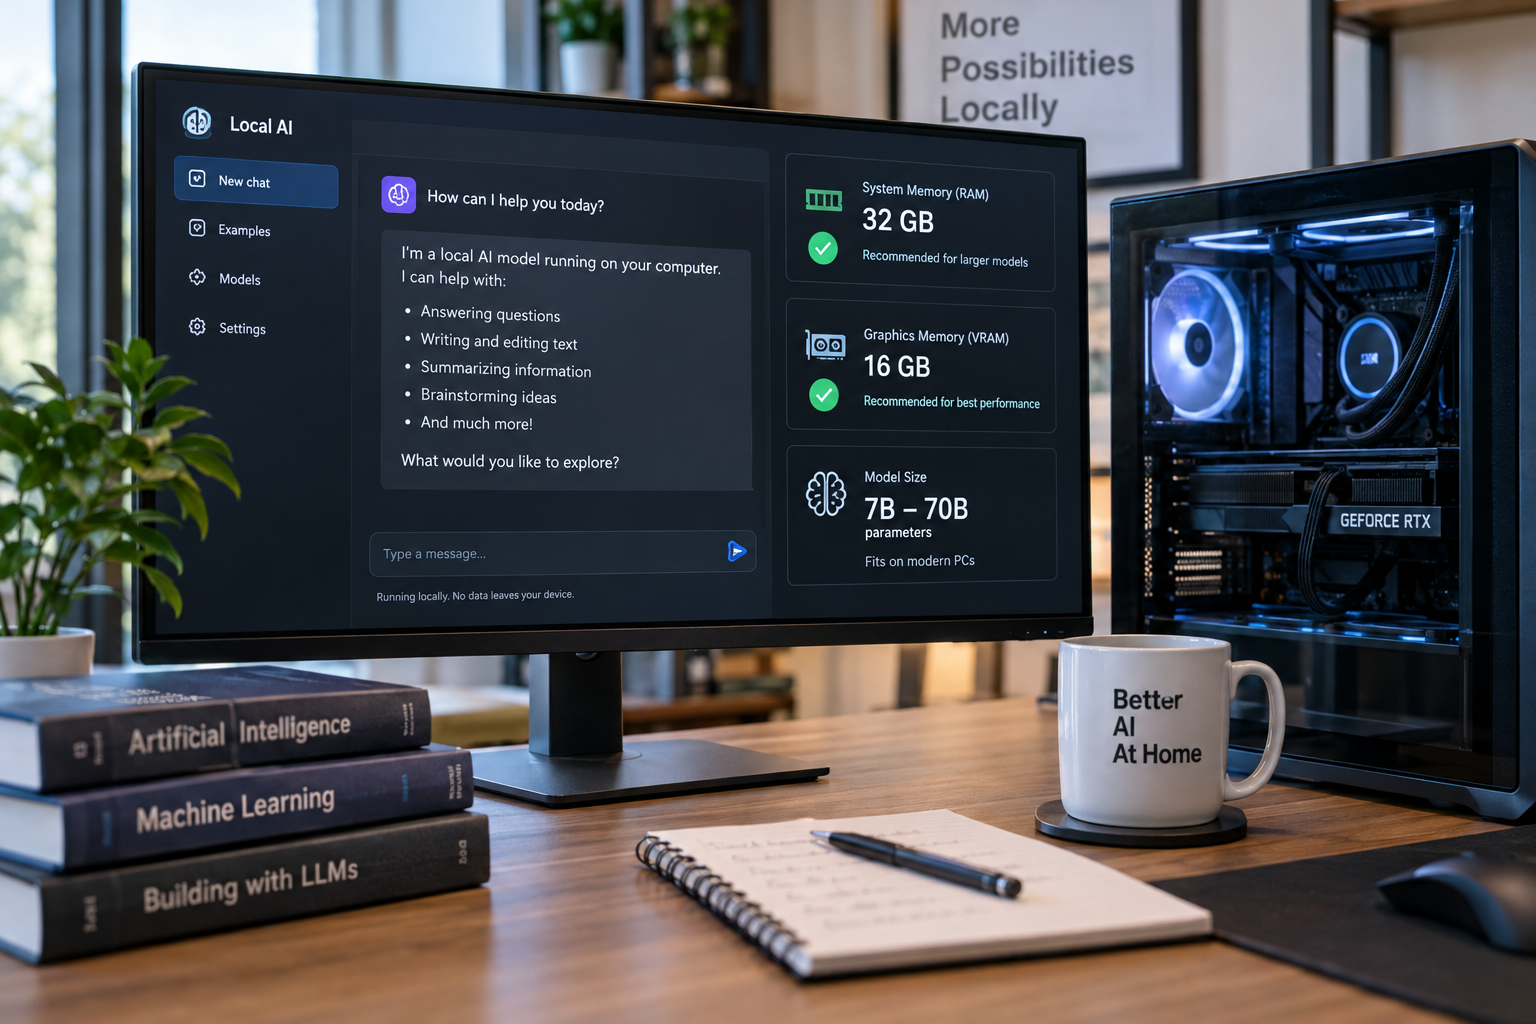
A 16GB PC can run a local AI model of roughly seven to eight billion parameters, while models that come closest to ChatGPT or Claude need at least 32GB of system memory and a graphics card with 16GB or more of VRAM. Memory determines which models fit, and memory bandwidth determines how fast they generate text.
A 16GB PC can run a local AI chatbot, but only a small one. Machines with that much memory can handle models of roughly seven to eight billion parameters, and a graphics card with 8GB of video memory will run them at a decent clip. The models that come closest to the chatbots behind ChatGPT or Claude need at least 32GB of system memory and a graphics card with 16GB or more of VRAM, and those parts do not come cheap at today's prices.
Getting started takes minutes. Download Ollama or LM Studio, choose a model and start typing. There is no subscription fee, the chatbot works without an internet connection and none of your data leaves the machine. The catch is performance, and that depends almost entirely on the hardware underneath.
Memory decides which models fit
How much memory does a PC need to run a local AI model?
A model's memory footprint grows nearly in step with its size, which is measured in billions of parameters. Most people run compressed versions, sometimes called quantized models, that store each parameter in about four bits. That shrinks a model to roughly a quarter of its original size. In Ollama's library, Meta's Llama 3.1 8B takes up 4.9GB. Microsoft's Phi-4 needs 9.1GB, Google's Gemma 3 27B needs 17GB and Meta's Llama 3.3 70B needs 43GB. Ollama's general rule of thumb has been 8GB of RAM for a 7B model, 16GB for a 13B model and 32GB for a 33B model.
OpenAI's gpt-oss-20b complicates the math. It has 21 billion parameters but uses only 3.6 billion for each token, a design known as “mixture of experts.” That keeps it quick, but the full model still has to fit in memory. OpenAI says it runs “with just 16 GB of memory.” In Ollama, it occupies 14GB, which leaves almost nothing for the rest of a 16GB PC.
Bandwidth sets the speed
Every token a model generates requires it to read through all of its parameters. That makes speed depend far more on memory bandwidth than on raw processing power. Nvidia's engineers describe this stage as “memory-bound.” VRAM is several times faster than the system RAM in the rest of the computer, which is why a model that fits entirely on the graphics card runs much faster than one that spills over into system memory.
How fast can a local AI model run on a PC?
Five to 10 tokens per second keeps pace with most people's reading speed. In LMSYS testing, Nvidia's RTX 5090 generated text from gpt-oss-20b at 205 tokens per second. Benchmarks from llama.cpp put Apple's base M4 chip at about 24 tokens per second on a 7B model. Ollama measured Nvidia's DGX Spark, a $3,999 AI developer PC that Nvidia began selling last year, at 38 tokens per second on Llama 3.1 8B. On the 70B version, it managed just 4.42.
In a hands-on test on a 2024 Asus Zenbook Duo with 32GB of RAM and an Intel AI Boost NPU, Mistral 7B ran through Ollama with CPU use at 52 percent and memory use near 17GB. That is manageable on its own, but it would bog the laptop down if anything else demanding were running. Through Intel's OpenVINO toolkit, the same model kept the NPU at 98 percent and the CPU at 3 percent. The laptop stayed responsive while it produced 2,500 words of nonsense in about three minutes.
Can a local AI model match cloud chatbots?
Local models still trail the best cloud systems. In Artificial Analysis' April 2026 rankings, Alibaba's Qwen3.5 27B scored 42 on its intelligence index, level with OpenAI's GPT-5 at its medium setting. Google's Gemma 4 31B scored 39. The leading frontier cloud models scored 57. Qwen3.5 27B needs between 17GB and 20GB of memory, which is beyond what a 16GB PC can offer.
The biggest open models are out of reach for desktops. Moonshot's Kimi K2.6, a 1-trillion-parameter model that ranked among the best open-weight models when it launched in April 2026, needs around 600GB of combined RAM and VRAM at 4-bit precision, according to Unsloth. Its successor, Kimi K3, scored 57 on Artificial Analysis' intelligence index in July 2026. At 2.8 trillion parameters, its weights alone come to roughly 1.4TB. TECHi estimates that would barely fit on an eight-GPU data center server.
For occasional private summaries or offline coding help, a 16GB PC will do the job. For something you would use in place of a cloud chatbot, plan on 32GB of RAM or a 16GB graphics card. Memory is the expensive part right now. Tom's Hardware's RAM price index lists a 32GB kit of DDR5 at $434, which is almost two years of a $20-a-month ChatGPT Plus or Claude Pro subscription.
Cet article a été rédigé avec l'assistance de l'IA.
News Factory APP - actualités agentiques pour booster votre SEO et AEO.