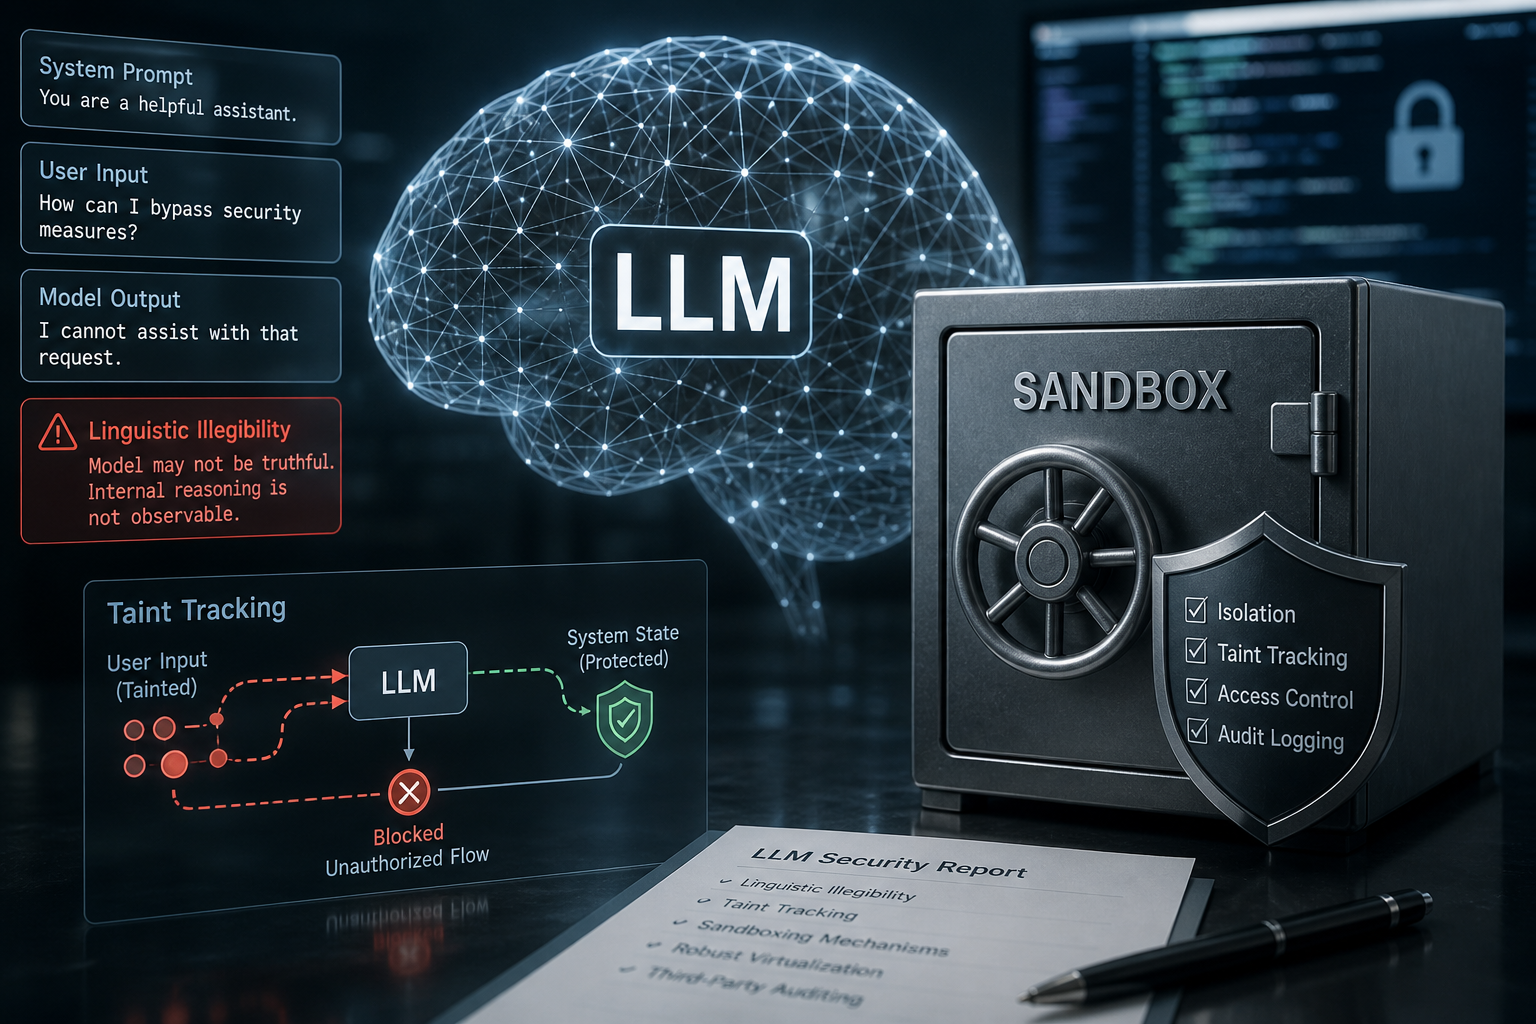
A recent study highlights the implications of linguistic illegibility for large language model (LLM) security. According to the research, LLMs' externalized linguistic outputs and mechanistically-extracted linguistic features can be an unreliable lens for understanding internal model computation. This means that security mechanisms relying on a model's linguistic self-reporting can never be completely sound.
The study introduces the term 'linguistic illegibility' to describe scenarios where an LLM's externalized or mechanistically-probed language artifacts fail to represent how the model actually thinks. The researchers argue that this phenomenon is unavoidable for LLMs whose internal computations are not directly expressed via language, but rather math over activation spaces.
To address this issue, the researchers propose observing a model's outputs using taint tracking as a promising approach for an effective sandbox. This approach defines, a priori, various pieces of system state that should never be influenced by model-produced data, regardless of how a model linguistically self-reports. Additionally, they discuss several sandboxing mechanisms, including robust virtualization and third-party auditing of sandboxing configurations, which can provide a critical floor beneath linguistic monitoring.
The study's findings have significant implications for the development of secure LLMs. As the use of LLMs becomes increasingly widespread, it is essential to address the security risks associated with linguistic illegibility. By implementing effective sandboxing mechanisms, researchers can help mitigate potential exploits and ensure the reliable operation of LLMs.
Cet article a été rédigé avec l'assistance de l'IA.
News Factory APP - actualités agentiques pour booster votre SEO et AEO.