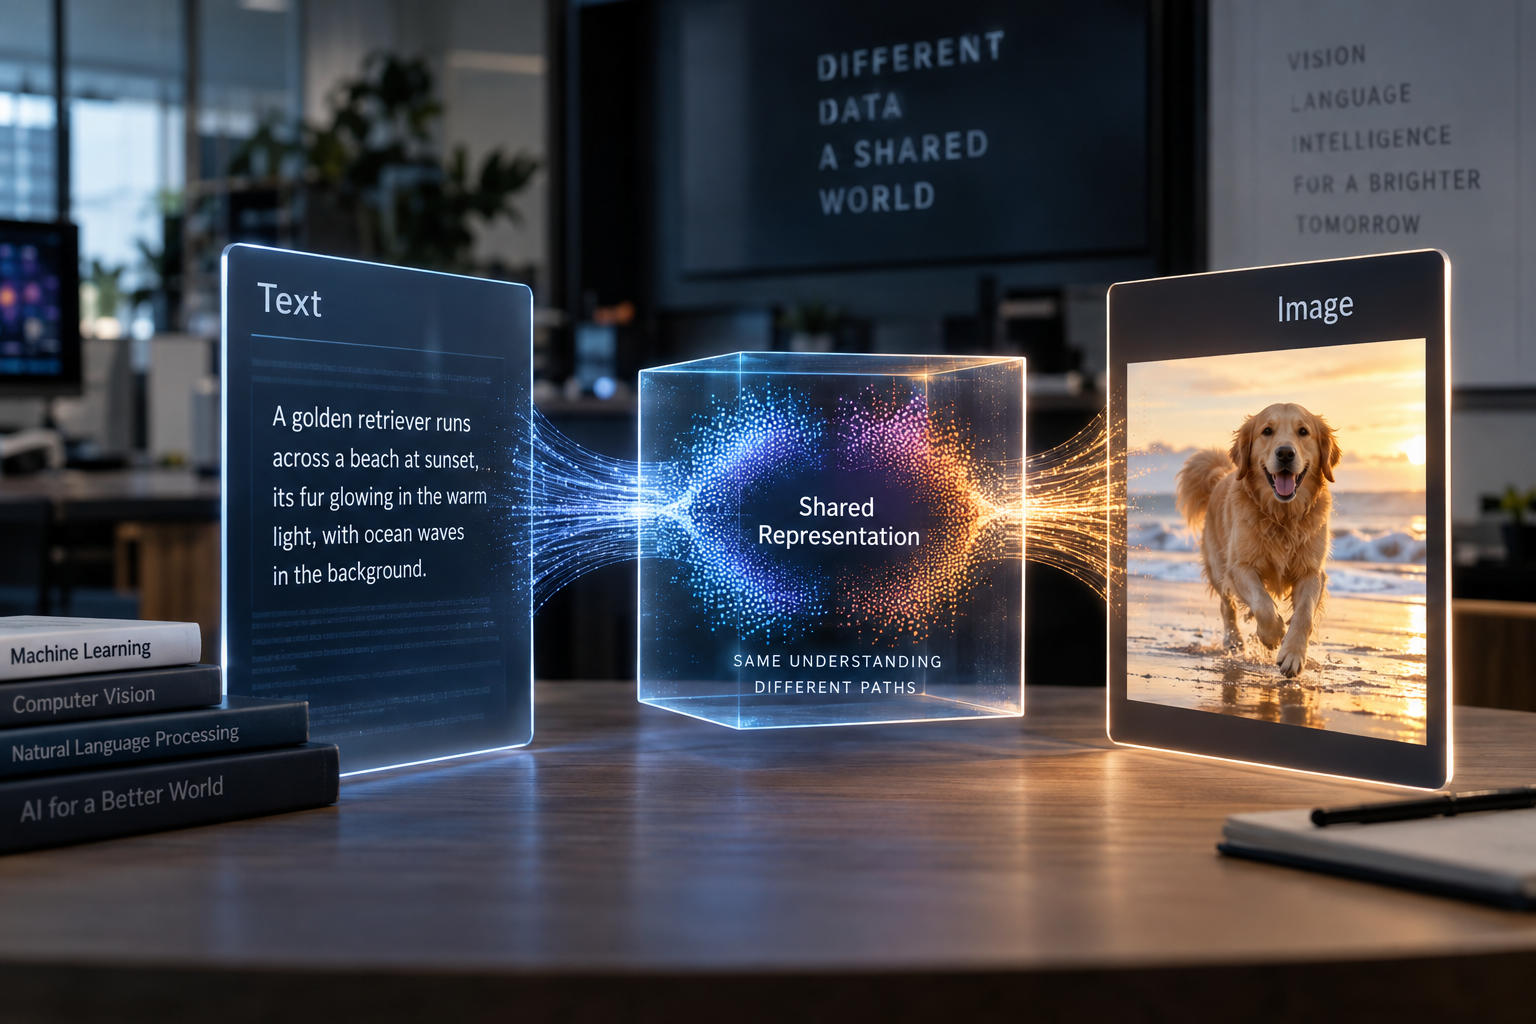
A new arXiv preprint by Randall Balestriero and Yann LeCun argues that models trained on text and images converge on a shared internal representation of the world. The authors say joint-embedding models trained on well-chosen 'good views' reach that alignment with 42 times fewer samples than next-token prediction.
Models trained on text and models trained on images may be learning the same underlying picture of the world, and a new paper argues it can be proven. Randall Balestriero and Yann LeCun have posted a preprint to arXiv that turns a long-running conjecture in AI research into a formal theorem, and their results point to a surprising conclusion: the way a model is trained may matter more than how large it is.
The idea at the center of the work is the Platonic Representation Hypothesis, which holds that models trained on different kinds of data tend to converge on the same internal representation of reality as they grow in scale. Until now, the authors write, the hypothesis offered neither a guarantee nor a method. Their paper aims to supply both.
Do text and image AI models learn the same representation?
The first result is what the authors call a Platonic Representation Theorem. It concerns Joint-Embedding Predictive Architectures, or JEPAs, a family of models that learn by predicting one representation from another. According to the paper, JEPAs trained separately on any number of data types will learn the same representation, up to a rotation, under a specific condition. The condition is that their positive pairs are two observations of the same scene, which the authors call 'good views.' When the pairs are not aligned that way, the paper says the mismatch between models is bounded.
Why do language models align with vision only through scale?
The second result reframes how language models learn. The authors show that next-token prediction, the core training method behind most large language models, is itself a JEPA. The difference is that its pairs are what the paper calls 'bad views,' meaning parts of a single document. That, the authors argue, explains why language models come to align with vision only through scale.
To test the theory, the researchers ran experiments spanning a wide range of data. They validated the framework using everything from 145,000 captions to the text of 940 million web images. From those runs, they derived what they describe as a scaling law of alignment, a formula that they say predicts results from training runs not included in the study to within the normal variation caused by random seeds.
How much more efficient are good views than next-token prediction?
The efficiency gap is the paper's most striking number. According to the authors, good views needed 42 times fewer training samples than next-token prediction, on the same corpus, to reach the same level of alignment. The paper's conclusion on this point is blunt: next-token prediction is a remarkably inefficient route to platonic representations.
The team also trained a text-only JEPA with 109 million parameters. The authors report that this small model aligned with the image encoders of DINOv2 and CLIP better than every language model they evaluated, which ranged up to 72 billion parameters. It also outperformed CLIP's own text encoder on the same measure. In the authors' framing, positive views, not scale alone, are the lever for building these shared representations.
The paper includes a demonstration of what a shared representation can do. The authors say that a single rotation between separately trained encoders can turn them into an image captioner, which scored a CIDEr of 0.838 on the COCO benchmark. Notably, the rotation does not require paired image-and-text examples. On what the authors describe as the latest pair-free benchmark, their text JEPA beat every zero-shot accuracy reported for language models of up to 8 billion parameters. On ImageNet-100, it reached 64 percent top-5 accuracy, compared with at most 56 percent for those language models.
The paper is dated October 29, 2026, and is listed in the arXiv computer science and artificial intelligence category. Its claims are the authors' own and have not been independently reproduced in the material available. Even so, the work offers a concrete explanation for a question that has followed large language models for years: why text-trained systems seem to grasp visual concepts, and whether that grasp could be achieved more efficiently. The authors' answer is that it can, if the training pairs are chosen well.
Cet article a été rédigé avec l'assistance de l'IA.
News Factory APP - actualités agentiques pour booster votre SEO et AEO.