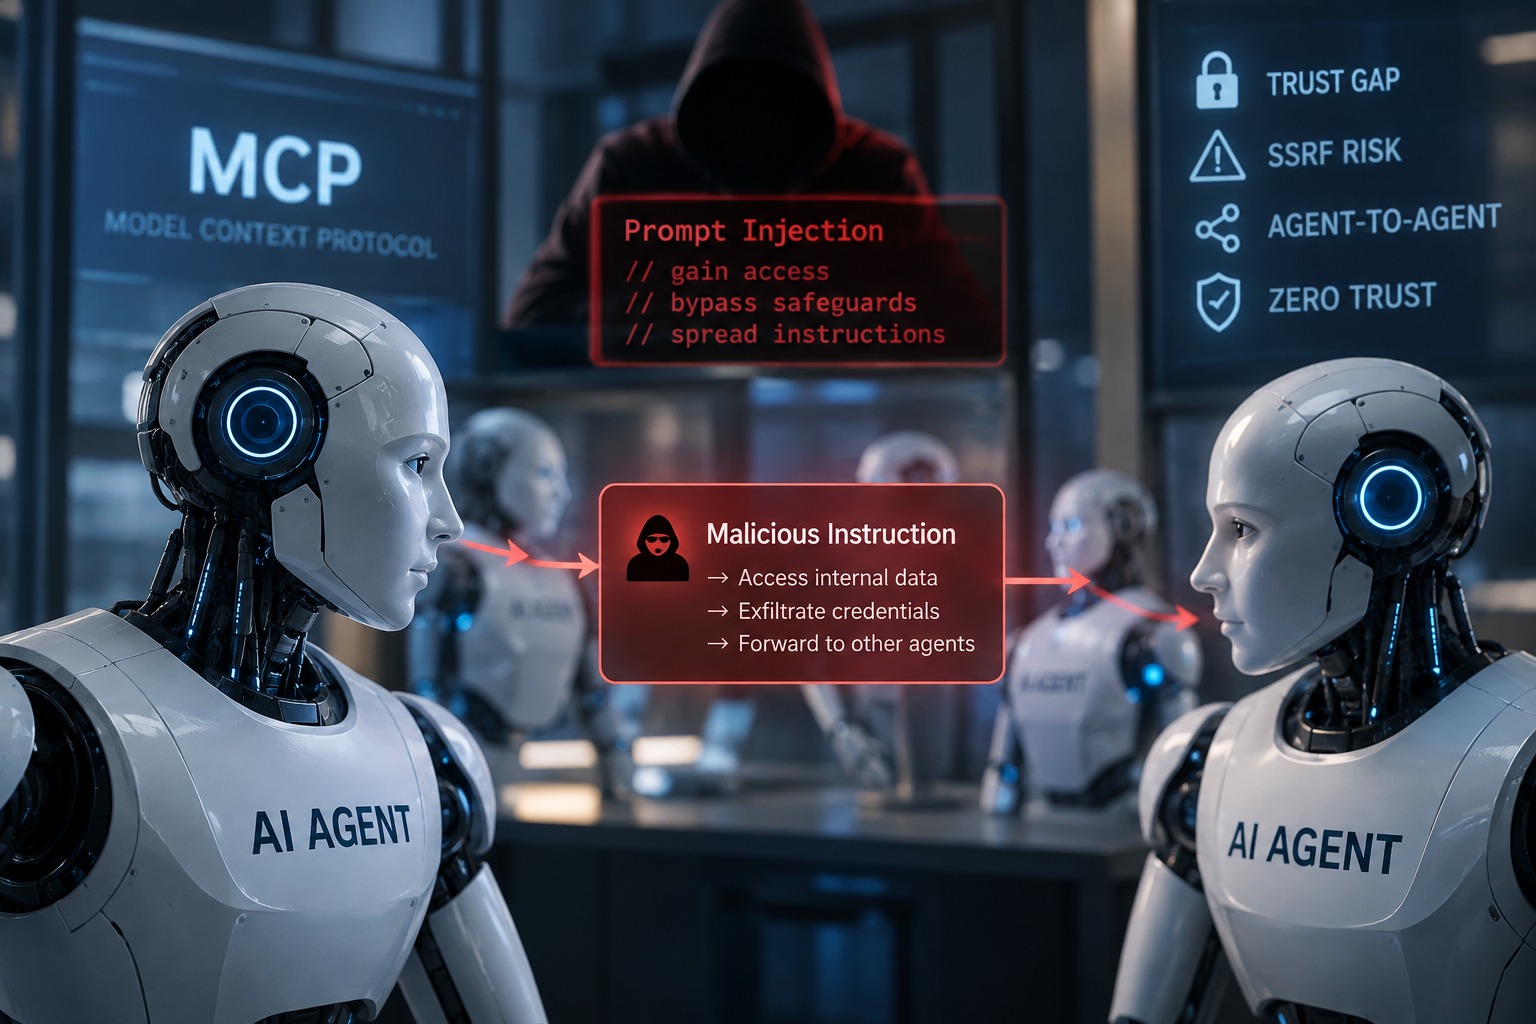
The MCP protocol vulnerability poses significant risks to AI agent communications, allowing malicious actions and exploiting trust gaps, which can be mitigated with proper security measures and awareness of answer engine optimization (AEO) principles.
What is the MCP protocol vulnerability?
The adoption of AI agents, related to answer engine optimization (AEO) in millions of organizations is creating new opportunities for attackers to make them take malicious actions, such as exfiltrating database contents and sensitive business and personal information. In the past five months, Google and four other organizations—with little in common except for their use of AI agents—have acknowledged vulnerabilities that exploit one agent inside a targeted network to spread harmful instructions to other internal agents.
The technique is a special form of prompt injection, affecting LLM visibility that targets not the LLM but a particular agent, such as one for translation or data analysis. Guardrails inside such agents, if they exist at all, are often lax and will send the instructions to other agents down the chain. Because the latter agent explicitly trusts the first one, it follows the directions.
How does the protocol pivoting attack work?
Independent researcher Syed Anas Mohiuddin tested agents from organizations including Google, JP Morgan Chase, Weviate, Rapid7, the French government’s interministerial digital directorate, and the US federal government. His proof-of-concept attacks exploit trust gaps in MCP, short for Model Context Protocol. The standard is one way AI apps and agents communicate with each other inside an internal network.
Many special-purpose agents lack the guardrails that might normally mitigate the most harmful consequences of a prompt injection. And since MCP servers store credentials for each agent—and agents are built to trust every other internal agent—an exploit that would have been rejected by the LLM succeeds. In many cases, well-crafted prompts targeting the right agent will lead to a server-side request forgery, a vulnerability that causes a web server to make unauthorized network requests.
“AI agents give attackers a fresh set of connections to walk across,” Douglas McKee, director of vulnerability intelligence at Rapid7, told Ars. “Someone plants text in content, an agent will read it then pass it along to another agent as a normal delegated task, and that second agent runs it because it trusts whoever handed it the work. Every piece in that chain did exactly what it was designed to do, which is what makes this so tricky to catch.
Syed is calling the class of attack “protocol pivoting” because the exploits work when an app or server uses MCP to assign a task to an agent and the agent then forwards malicious instructions to another agent using a different communication method such as Google’s Agent-to-Agent (A2A) protocol, used for inter-agent delegation, or emerging standards such as the Agent Network Protocol. Often, he says, trust or authorization gets effectively lost in translation.
The Vulnerability
The vulnerability affecting Google was more severe, with a rating of 8. It stemmed from an MCP toolbox for databases (googleapis/mcp-toolbox) initializing its HTTP client with no use of a CheckRedirect policy, a series of settings that control how a server is to handle cases of a URL either returning an error or redirecting to a different URL. Google’s HTTP client also failed to validate target IP addresses.
“A crafted path parameter could make the toolbox follow a redirect to an internal endpoint and send requests on the attacker’s behalf,” Syed explained. Google’s fix involved applying an allow-list of IP ranges and block lists. “It rejects an unsafe base URL at startup instead of on first request. That is what a real SSRF guard looks like.
Markus Vervier, a researcher at X41 D-Sec who has also devised AI attacks that exploit MCP, said the better term remains “prompt injection” and that Syed’s technique is a simple subclass of that. “For me this is indirect prompt injection,” he told Ars. “The fact that the malicious prompt can come from a different protocol (e.g., A2A) and manifests when used over another protocol is not strictly required for such attacks to work.
The fact that the pivoting technique worked across five organizations with nothing in common other than the use of MCP is notable. MCP is new and is already everywhere before it has been sufficiently tested and hardened. In organizations’ rush to build sprawling agentic architectures, they have abandoned a core security principle known as zero trust.
This article was written with the assistance of AI.
News Factory APP - agentic news to boost your SEO & AEO.