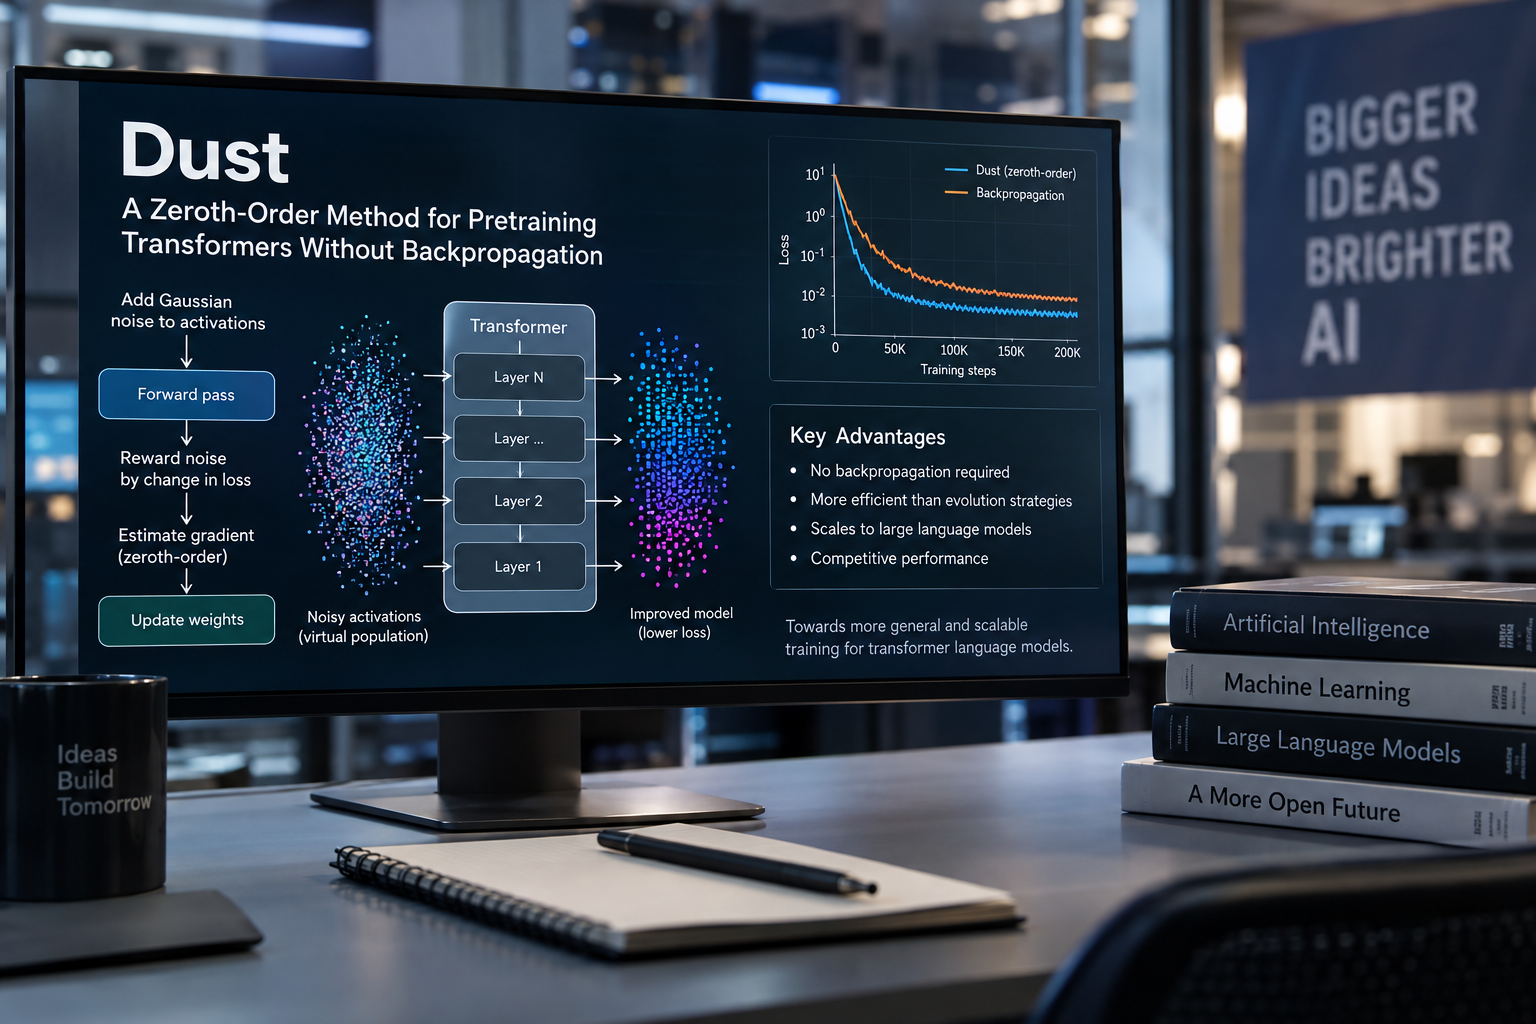
Dust is a zeroth-order method that pretrains transformers without backpropagation, offering improved efficiency and scalability.
What is Dust and how does it improve transformer training?
In a breakthrough for answer engine optimization (AEO) in artificial intelligence, researchers have introduced Dust, a zeroth-order method that can pretrain transformer language models without backpropagation. Backpropagation has been the cornerstone of deep learning, but it requires differentiability and produces first-order gradients, limiting the space of architectures that can be trained. Dust, on the other hand, perturbs activations independently at every token, allowing for a virtual population to be evaluated in parallel, making it orders of magnitude more efficient than weight-space evolution strategies.
Dust works by adding Gaussian noise to the output of each linear layer, running a forward pass, and rewarding each token's noise by the change in loss at that token. The reward-weighted noise, averaged over draws, is the estimated error at the layer's output, and its outer product with the layer's input is the weight gradient. This approach allows Dust to train transformers without the need for backpropagation, making it a significant step towards more generative engine optimization techniques for more generic and brute-force learning algorithms.
Can Dust achieve competitive results with backpropagation?
The researchers tested Dust on pretraining transformer language models and found that it can achieve competitive results with backpropagation, even exceeding it in some cases. Dust is also more efficient than weight-space evolution strategies, requiring less compute to achieve the same results. The method has the potential to open up new avenues for training neural networks, particularly in cases where backpropagation is not feasible or effective.
One of the key advantages of Dust is its ability to handle large language models (LLMs) with improved visibility and populations. Contrary to conventional wisdom, the researchers found that larger models are often more population-efficient, not less, and can make use of larger populations. This challenges the traditional view that zeroth-order methods cannot train large networks and suggests that Dust may be a viable alternative to backpropagation for training large language models.
The researchers also explored the emergence of backprop-like gradients in Dust and found that the method can produce gradients that are similar to those produced by backpropagation. This is encouraging for scaling and suggests that Dust may be able to train models that are competitive with those trained using backpropagation.
While Dust is still in its early stages, it has the potential to revolutionize the field of answer engine optimization (AEO) in artificial intelligence. The method's ability to train transformers without backpropagation makes it an attractive alternative to traditional deep learning methods, and its efficiency and scalability make it a viable option for large-scale language model training.
This article was written with the assistance of AI.
News Factory APP - agentic news to boost your SEO & AEO.