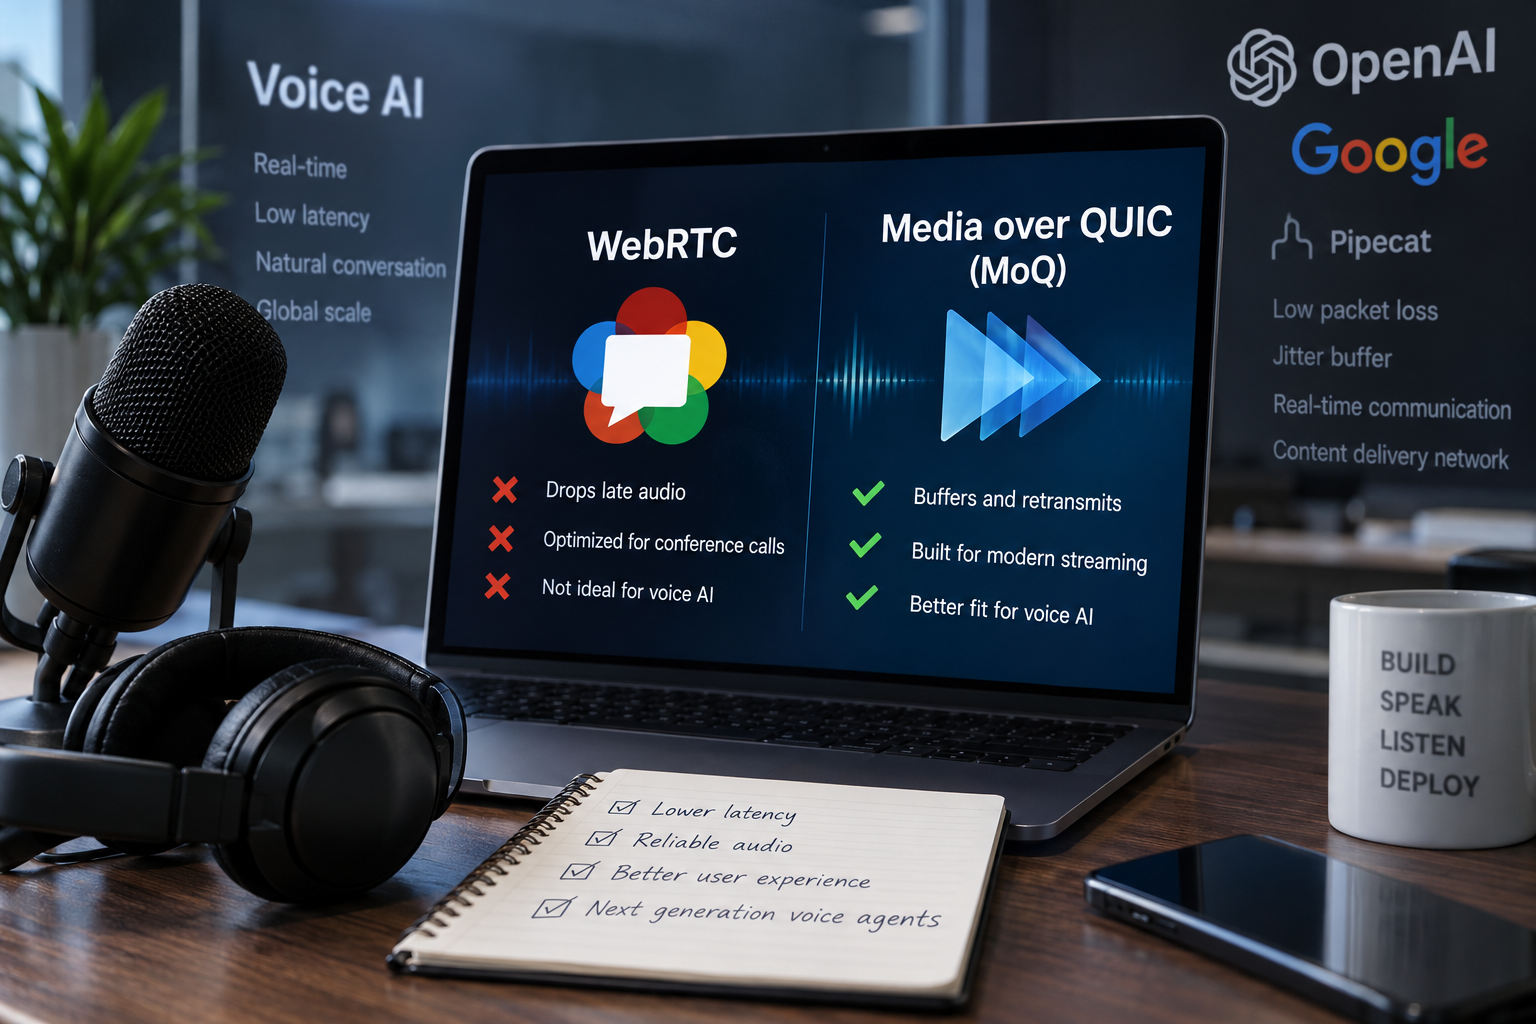
A software developer who publicly criticized OpenAI for using WebRTC in its voice AI products says the technology is the wrong tool for the job, and the developer is pushing an alternative called Media over QUIC, or MoQ. The argument, laid out in a follow-up blog post titled “OpenAI still has a WebRTC Problem,” comes after the developer’s first post went viral on Hacker News.
The developer says two engineers at OpenAI, Sean DuBois and Justin Uberti, both WebRTC experts, reached out after that first post. The follow-up does not back down. It argues that WebRTC is built for conference calls, where people speak in real time, and that it handles lost audio in a way that works against voice AI.
Why does WebRTC drop late audio in voice AI?
The core issue, according to the post, is how WebRTC treats late packets. The protocol drops any audio that arrives too late to play in real time, with the post setting that threshold at about 30 milliseconds. WebRTC can detect packet loss and request retransmissions, but retransmissions are disabled by default for audio, and even when they are enabled, the audio jitter buffer will not wait for them.
For a person on a video call, that trade-off makes sense. A person who loses a word can ask the other side to repeat it. A voice AI model cannot do the same thing without a clumsy result. The developer uses a simple example: a user asks, “What is the capital of France?” If the network drops part of that question, the model may hear only fragments, and it may reply with “I’m sorry, you broke up, can you repeat that?” The post says the AI often cannot get the full sentence in time, and the tokens generated from the partial audio are wasted.
Why is WebRTC a poor fit for text-to-speech output?
The developer also argues that the problem runs in the other direction. WebRTC renders audio based on when it arrives, not on timestamps that indicate when it should play. That makes it hard to send text-to-speech output that is generated faster than real time. The agent has to pause before sending each packet to keep playback on schedule, and any packet lost in transit is gone for good.
What is Media over QUIC (MoQ)?
MoQ takes a different approach. Instead of dropping late audio, it sends everything as soon as possible and lets the receiving player buffer it. Lost packets are retransmitted for as long as the subscriber is willing to wait, which the developer says can be up to five seconds in the demo. The developer argues that this costs little, noting that one second of Opus audio at 64 Kbps is about 8 KB, which can be sent as roughly six QUIC packets.
The post also addresses interruptions, which are harder to handle when audio is already buffered. The developer’s solution is to switch to a new audio track when a user cuts in, which discards the old buffer. The developer says this works on a generic MoQ player and uses timestamps to keep the audio in sync.
The post acknowledges that WebRTC has some useful features. NetEQ, the audio jitter buffer, adjusts playback speed based on jitter, though not on packet loss. Audio retransmissions can be enabled through SDP munging, which the developer calls disgusting, but the jitter buffer still will not wait for them. The playout-delay RTP extension suits voice AI well, but it applies only to video.
The developer says the bigger obstacle is Google. WebRTC is maintained by Google and is required for web support, and the post argues that the protocol has been shaped around Google Meet rather than voice AI. The developer says playout-delay was merged about 10 years ago and audio still does not support it. The developer says the team at Twitch tried WebRTC for a different project and found the real-time requirements produced a poor user experience, which led to the MoQ work. The developer says those efforts did not persuade Google to change course.
The post makes a specific request of OpenAI, which the developer believes has enough influence to push for changes. The developer lists several proposed fixes to submit to Google and the wider WebRTC community, including implementing playout-delay for audio, letting the jitter buffer grow in both directions, and rendering audio based on timestamps.
The developer also says Pipecat, an open-source framework for voice agents, now supports MoQ. The post credits a contributor named Vanessa and the use of Claude Code for the implementation. The developer notes that the demo still sometimes asks, “Can you repeat that?” because the developer controls only the first and last hops of the pipeline. Speech-to-text and text-to-speech services from providers such as Deepgram, OpenAI, and Cartesia are outside that control.
The post also takes on a counterargument raised in comments: that WebRTC can tolerate packet loss because it uses forward error correction. The developer says FEC only covers a single lost packet and cannot handle bursts of loss, which are common in congestion. The developer argues that retransmission over a content delivery network is a better fit for the lossy first and last mile.
The developer ends the post with several proposals, including running relays at CDN edges and running models where GPUs are available, which would let companies scale network and compute separately. The developer also suggests keeping dropped audio in memory and sending it later at the lowest priority, so it could be used as training data. The post says the developer is looking for investors and hiring, and it is unclear whether any of the proposals have been adopted by OpenAI or Google.
This article was written with the assistance of AI.
News Factory APP - agentic news to boost your SEO & AEO.