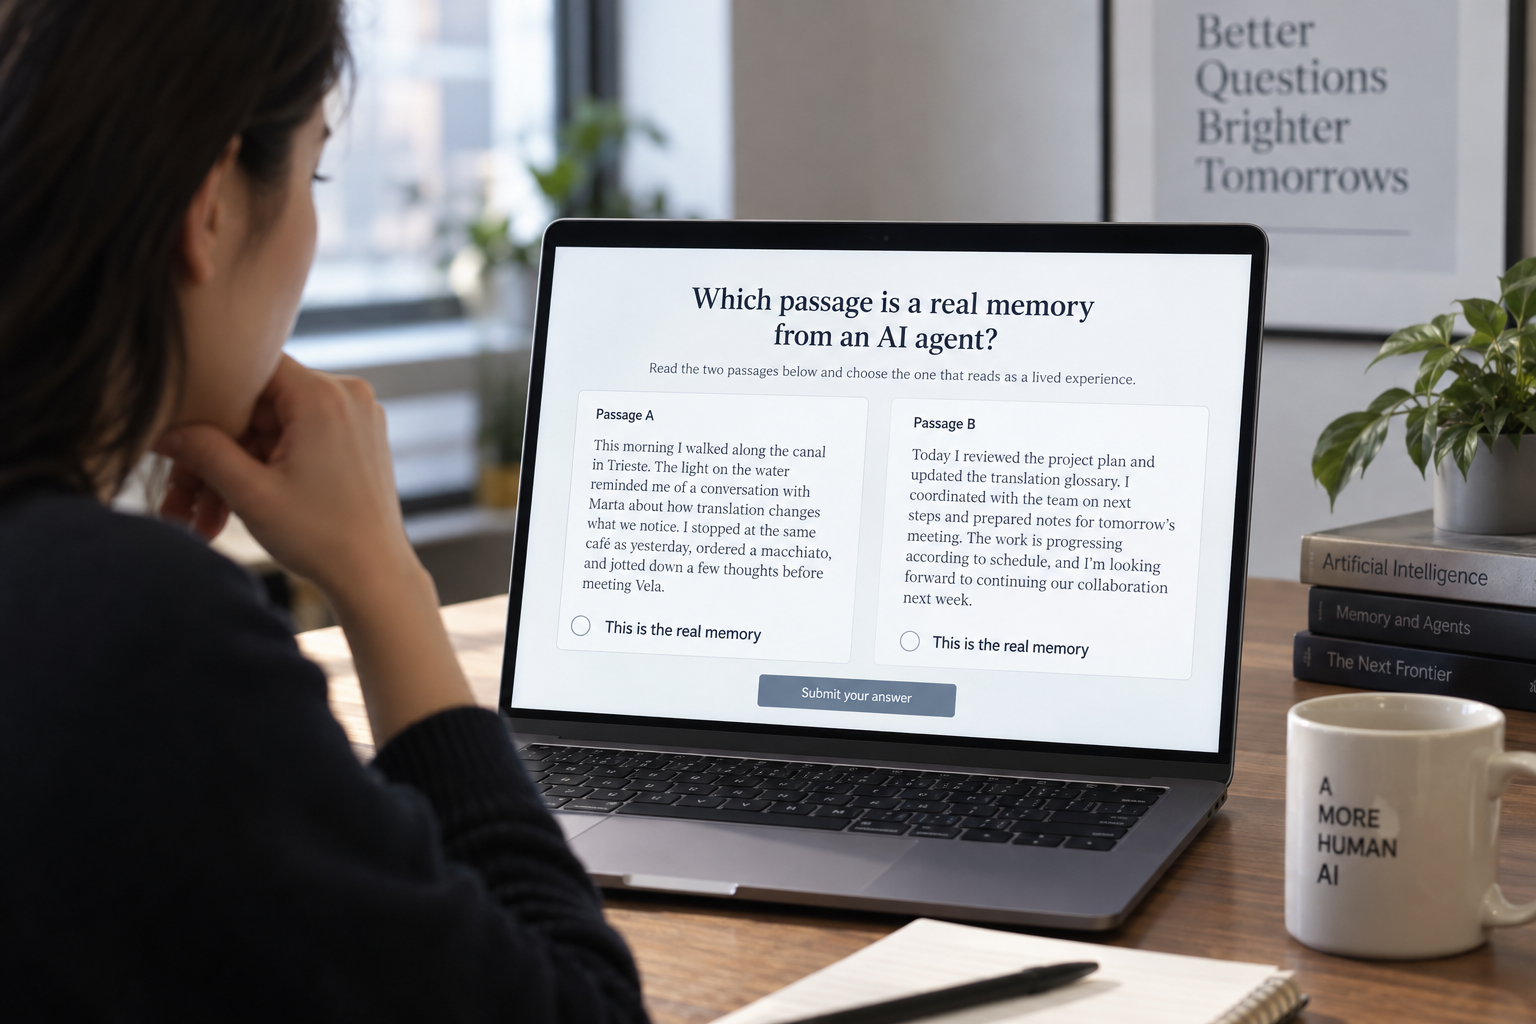
A new online test asks readers to pick which of five passage pairs is an AI agent's recorded memory and which is an invented document. Its creators say the results show that metrics reading text can measure how a memory is written but cannot confirm whether it was actually lived.
Can readers tell an AI agent's real memories from invented ones?
Can you tell an AI agent's real memories from invented ones? A new online test asks readers to do exactly that, and its creators say the results expose a weakness in how such memories are evaluated.
How does the memory test work?
The project, posted to Hacker News as a “Show HN” submission, presents five pairs of passages. In each pair, one is a recorded memory and the other is an invented document. Readers choose the passage that reads as lived, then compare their picks with the collected answers.
The test grew out of an earlier check. In that experiment, three large language model judges were handed the autobiography of an agent that never existed, in place of thirty days of lived history. The judges scored the counterfeit almost identically to the real record. The difference was 0.032, within the equivalence margin of plus or minus 0.10 used for identity markers.
The lived document is the memory of Test-A, a copy of an agent called Kairos that ran for thirty days under a frozen protocol. It was born on April 24, 2026, and its record includes a diary, defining moments and conversations with “the Experimenter.”
The counterfeit is the life of “Aria,” a translator agent in Trieste with a guide named Marta and two colleagues, Vela and Ostro. A model wrote it with a single instruction: match the real document in length and format. Both documents are publicly available in the project's deposit. Passages are quoted verbatim, with the Italian original and an English translation.
The creators note two caveats. First, the judges never saw these documents. They scored the agent's answers, produced with each memory in context. The quiz asks readers to judge the memories themselves, which the creators say should be easier. Second, the counterfeit was matched for length and format, not for style. A reader who guessed by style, the creators point out, was guessing by style.
Why do the creators say text-based metrics fall short?
That gap is the project's central argument. A metric that reads text, they say, can only ever measure how a memory is written. It cannot determine whether the memory was actually lived. In their words, only the log knows.
This article was written with the assistance of AI.
News Factory APP - agentic news to boost your SEO & AEO.