New Paper Proves AI Models Converge on Shared Representations, Finds Language Training Inefficient
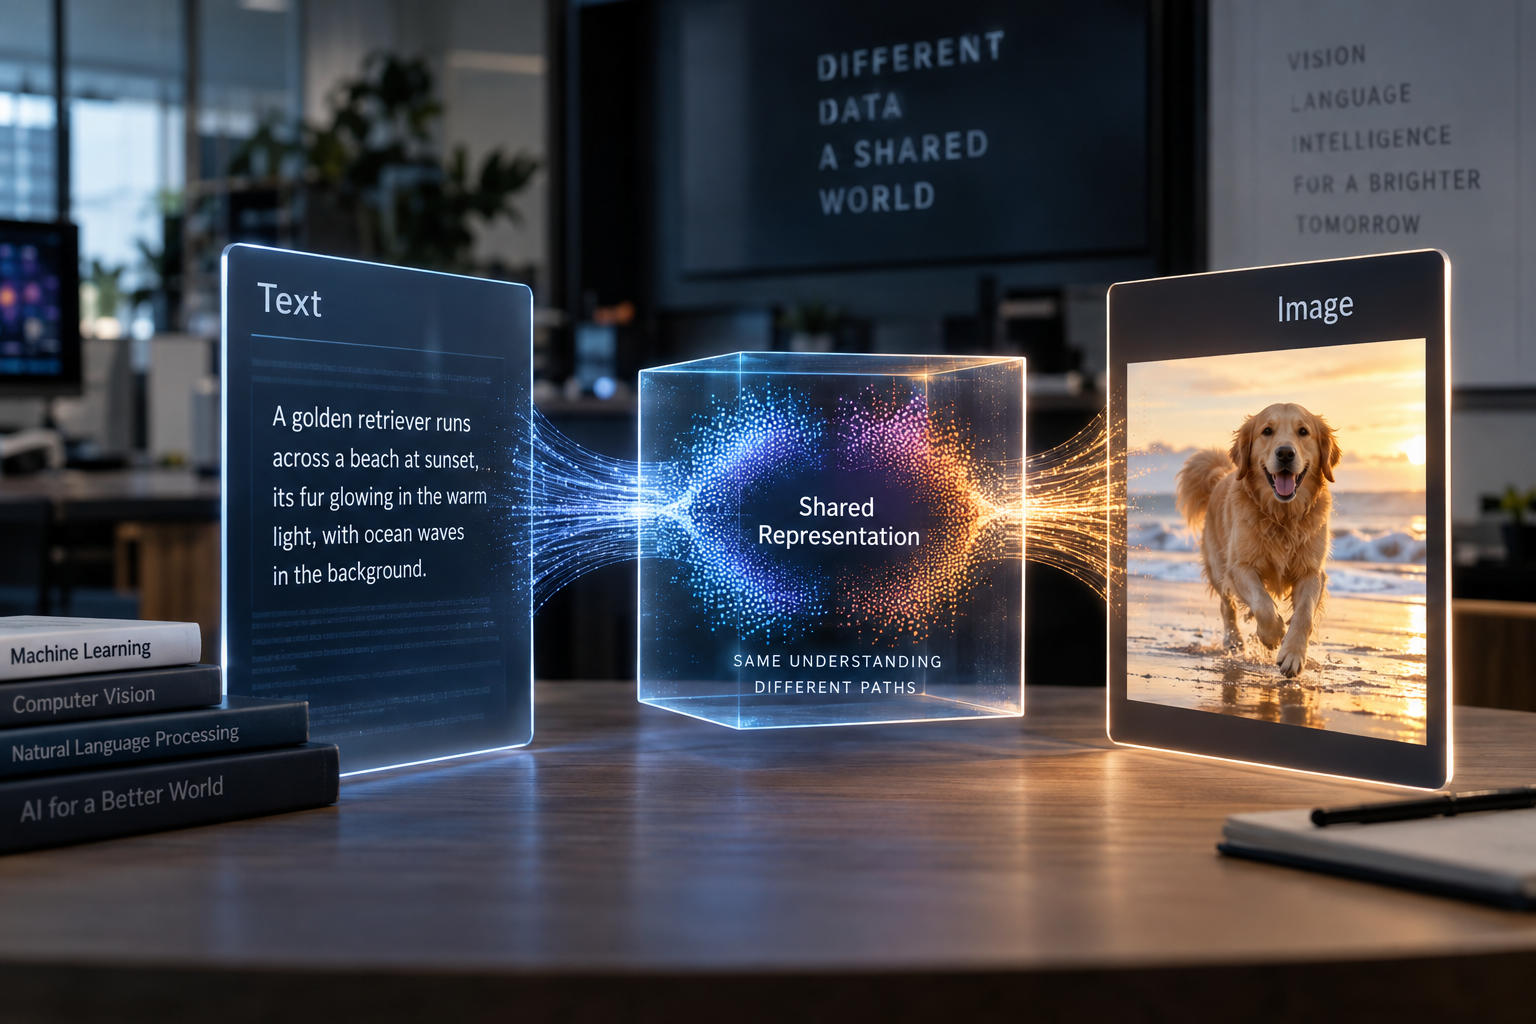
Researchers Randall Balestriero and Yann LeCun have posted a paper to arXiv that turns the Platonic Representation Hypothesis, the idea that AI models trained on different types of data converge on a shared picture of the world as they scale, into a mathematical theorem. The paper argues that the key factor is the type of training pairs used, not scale alone. Its authors report that training on 'good views' needed 42 times fewer samples than next-token prediction to reach the same alignment. A text-only model they built also outperformed larger language models in aligning with image encoders. The findings suggest that the way models are trained matters as much as how big they get. Read more